 README
- ::byte_alignBitReader::byte_align
- ::newBitReader::new
- ::read_bitBitReader::read_bit
- ::read_bitsBitReader::read_bits
- ::remaining_bitsBitReader::remaining_bits
- ::seekBitReader::seek
- ::skipBitReader::skip
- ::tellBitReader::tell
- ::total_bitsBitReader::total_bits
- ::decode_scalarCodebook::decode_scalar
- ::decode_vqCodebook::decode_vq
- ::decode_vq_setCodebook::decode_vq_set
- ::decode_vq_stepCodebook::decode_vq_step
- ::parseCodebook::parse
- ::decode_packetDecoder::decode_packet
- ::newDecoder::new
- TFloor
- ::decodeFloor0::decode
- ::parseFloor0::parse
- ::synthesizeFloor0::synthesize
- ::decodeFloor1::decode
- ::parseFloor1::parse
- ::synthesizeFloor1::synthesize
- ::buildHuffmanTable::build
- ::decodeHuffmanTable::decode
- ::parseMapping::parse
- TMode
- ::parseOggPage::parse
- ::segment_lenOggPage::segment_len
- ::total_sizeOggPage::total_size
- ::has_partialPacketAssembler::has_partial
- ::newPacketAssembler::new
- ::push_pagePacketAssembler::push_page
- ::decodeResidue::decode
- ::parseResidue::parse
- ::getVorbisComment::get
- ::get_allVorbisComment::get_all
- ::parseVorbisComment::parse
- ::parseVorbisInfo::parse
- ::parseVorbisSetup::parse
- ::channelsVorbisStream::channels
- ::granule_positionVorbisStream::granule_position
- ::is_readyVorbisStream::is_ready
- ::metadataVorbisStream::metadata
- ::newVorbisStream::new
- ::pcmVorbisStream::pcm
- ::push_pageVorbisStream::push_page
- ::sample_rateVorbisStream::sample_rate
- ::trim_to_granuleVorbisStream::trim_to_granule
- VFLAG_BOS
- VFLAG_CONTINUED
- VFLAG_EOS
- Vcompute_window
- Vdecode_ogg
- Vdecode_ogg_base64
- Vinverse_mdct
- Vogg_crc32
- Vogg_crc32_update
- Vparse_modes
- Vwav_encode_pcm16
moonvorbis
纯 MoonBit 实现的 OGG/Vorbis 音频解码器,不依赖任何 C 库或系统编解码器
vorbis
ogg
audio
decoder
codec
wasm
Author
Version
0.1.3
License
Apache-2.0
Repository
Last updated
yesterday
Downloads
11
Dependencies
- moonbitlang/x0.5.5
#moonvorbis
纯 MoonBit 实现的 OGG/Vorbis 音频解码器。不依赖任何 C 库或系统编解码器,
从字节流到 PCM 全部由 MoonBit 代码完成。
支持解码为标准 WAV、命令行批量转换,以及编译成 WebAssembly 在浏览器内直接播放。
#功能
- OGG 容器:页解析、segment table 重组、CRC-32 校验、packet 组装
- Vorbis 头部:identification / comment / setup 三个包头
- Codebook:Huffman 解码、VQ lookup type 1/2、sequence_p 累加、ordered 与 sparse 编码
- Floor 0:由 LSP 系数与幅度还原增益曲线
- Floor 1:曲线解码与合成
- Residue:type 0 / type 1 / type 2,含多声道交错 VQ
- 立体声耦合:magnitude/angle 反变换
- IMDCT 与重叠相加:含长短块(window switching)切换
- 元数据:comment 头里的 vendor 与 TITLE / ARTIST 等标签,按 key 查询(不区分 ASCII 大小写,支持同名标签重复出现)
- 输出:多声道 16-bit PCM WAV
#安装
作为依赖引入:
moon add LL728/moonvorbis下面的库示例和命令行入口都要读写文件,所以还得加上 moonbitlang/x——依赖不会
跟着包传递,只加 LL728/moonvorbis 的话 import "moonbitlang/x/fs" 会报
「containing module is not imported」:
moon add moonbitlang/x只用 decode_ogg 这类纯内存接口(传 Bytes、收 Result)的话,加
LL728/moonvorbis 一条就够,解码库本身不依赖 moonbitlang/x。
已发布到 mooncakes.io:https://mooncakes.io/docs/LL728/moonvorbis。
在本仓库内开发:
moon check --target wasm-gc
moon test --target wasm-gc#用法
#作为库使用
引入依赖后(见上文「安装」),解码只需 decode_ogg 与 wav_encode_pcm16 两步:
// moon.pkg
import {
  "LL728/moonvorbis",
  "moonbitlang/x/fs",
}

// main.mbt —— 把 in.ogg 解成 16-bit PCM WAV,并打印元数据
fn main {
  try {
    let data = @fs.read_file_to_bytes("in.ogg")
    match @moonvorbis.decode_ogg(data) {
      Ok(stream) => {
        let wav = @moonvorbis.wav_encode_pcm16(
          stream.pcm(),
          stream.sample_rate(),
        )
        @fs.write_bytes_to_file("out.wav", wav)
        println(
          "采样率 \{stream.sample_rate()} Hz,声道 \{stream.channels()},样本 \{stream.pcm()[0].length()}",
        )
        match stream.metadata() {
          Some(meta) =>
            match meta.get("TITLE") {
              Some(title) => println("标题: \{title}")
              None => ()
            }
          None => ()
        }
      }
      Err(e) => println("解码失败: \{e}")
    }
  } catch {
    @fs.IOError::IOError(msg) => println("I/O 错误: \{msg}")
  }
}
decode_ogg 一次性解完整文件,返回 Result[VorbisStream, String]。需要边收边解时改用流式入口
VorbisStream::new(),把 OGG 页逐块喂给 push_page,is_ready() 为真后即可读 pcm()——
两条路径共用同一套解码实现与 granule position 裁剪逻辑。
曲目信息走 stream.metadata(),返回 VorbisComment?(comment 头解析完成后为 Some)。
get(key) 取单值,get_all(key) 取同名标签的全部取值——规范允许同一个 key 重复出现,
例如多位 ARTIST。key 按规范不区分 ASCII 大小写,"title" 与 "TITLE" 等价;取不到时
get 返回 None,get_all 返回空数组。
#命令行
包内自带一份 demo/sample.ogg,clone 后可直接跑通:
moon run cmd/main --target wasm-gc -- demo/sample.ogg out.wav省略输出路径时写入 input.ogg.wav。文件里若有 TITLE / ARTIST / ALBUM 标签,
会一并打印出来(demo/sample.ogg 没有标签,所以上面这条命令只输出采样率与声道)。
#浏览器
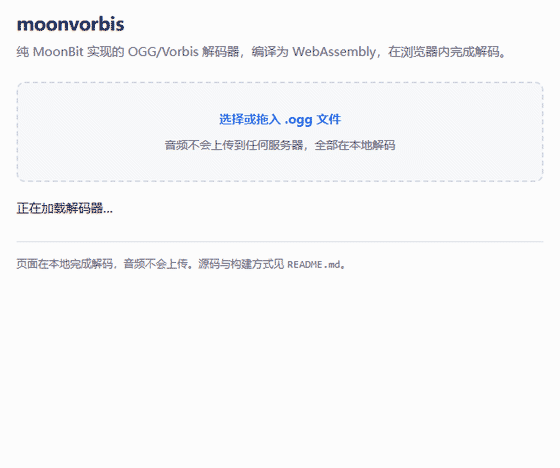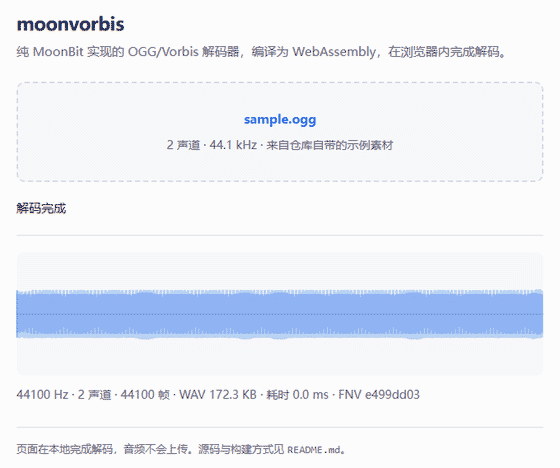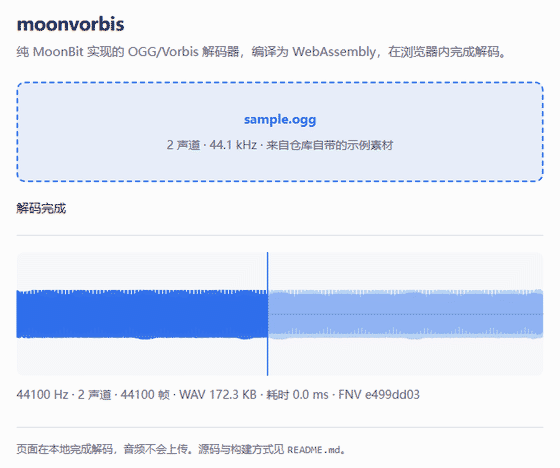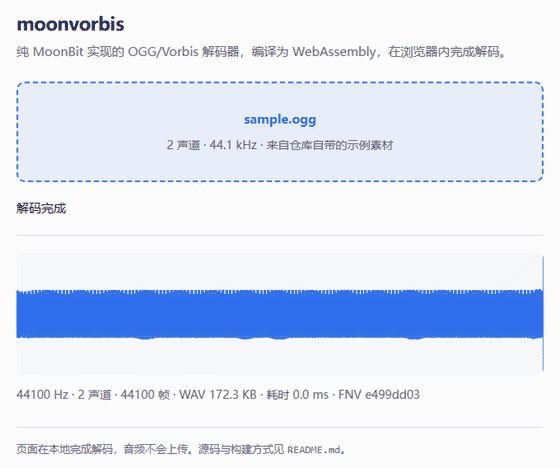
这段动画取自 demo/record.html 的完整流程:加载 wasm、选中 demo/sample.ogg、
解码、画出波形。波形与元信息都来自真实解码结果,不存在预置画面;页面按
?t=<毫秒> 渲染流程中的某一刻,tools/make_demo_gif.py 逐帧截图再合成 GIF,
所以重新生成的结果是稳定可复现的:
python -m http.server 8000      # 先在仓库根目录起服务
python tools/make_demo_gif.py
本地运行:
# 重新生成 demo/moonvorbis.wasm(仓库内已附带一份)
moon build --target wasm-gc --release
cp _build/wasm-gc/release/build/moonvorbis.wasm demo/

python -m http.server
# 打开 http://localhost:8000/demo/
页面在本地完成解码,音频不会上传。需要浏览器支持 WebAssembly JS String
Builtins:Chrome / Edge 130+、Firefox 134+,Safari 目前不支持。
#结构
| 文件 | 职责 |
|---|---|
| bitreader.mbt | LSB-first 位读取器,带越界检查 |
| ogg_crc.mbt | OGG 页校验用的 CRC-32 |
| ogg_page.mbt | 页头解析与校验 |
| ogg_packet.mbt | 跨页 packet 组装 |
| vorbis_info.mbt | identification 头 |
| vorbis_comment.mbt | comment 头解析与元数据查询(get / get_all) |
| vorbis_setup.mbt | setup 头,聚合下列子结构 |
| codebook.mbt | codebook 与 Huffman/VQ 解码 |
| huffman.mbt | Huffman 表构建 |
| floor0.mbt | floor0 解码与合成 |
| floor1.mbt | floor1 解码与合成 |
| residue.mbt | residue 配置与解码 |
| mapping.mbt | channel mapping 与耦合 |
| mode.mbt | block flag / mapping 选择 |
| mdct.mbt | IMDCT |
| window.mbt | 窗函数 |
| decoder.mbt | 解码主循环 |
| vorbis_stream.mbt | 高层编排:字节流 → PCM |
| wav.mbt | WAV 序列化 |
| wasm_api.mbt | WASM 导出接口 |
| cmd/main/ | 命令行入口 |
| CHANGELOG.md | 各版本的改动记录 |
| index.html | 项目主页(GitHub Pages 的根路径) |
| tools/verify.py | 对 libvorbis 的交叉验证脚本 |
| tools/vorbisgen.py | 按规范直接拼出 OGG/Vorbis 测试流 |
| tools/granule_sweep.py | 扫 granule position 裁剪行为 |
| tools/residue_sweep.py | 扫 residue 各条通路 |
| tools/floor0_sweep.py | 扫 floor 0 各条通路 |
| tools/wasm_contract.py | 静态校验 wasm 的导入/导出契约 |
| tools/wasm_smoke.mjs | 在 Node 里跑通 wasm 解码并与命令行产物比对 |
| tools/make_demo_gif.py | 逐帧截图并合成演示 GIF |
| demo/headless-test.html | 无头浏览器冒烟测试 |
| demo/decoder.js | 浏览器侧解码胶水,两个演示页共用 |
| demo/record.html | 演示录制页,按 ?t= 渲染流程中的某一刻 |
#测试
moon test --target wasm-gc    # 77 个用例
moon test --target js         # 同一套用例,js 后端
解码逻辑只用后端无关的 MoonBit 特性,两个后端跑的是同一套用例,CI 上都会跑。
默认目标是 wasm-gc(moon.mod 的 preferred_target),浏览器演示用的也是它。
单元测试验证的是「实现与理解自洽」,抓不到规范理解本身的偏差。作为补充,
tools/verify.py 从零生成已知内容的 OGG、用本解码器解出 WAV,再和 libvorbis
的输出比较相关系数与 RMS 误差:
python tools/verify.py --stereo            # 相关系数 0.9999
python tools/verify.py --stereo --noise    # 相关系数 0.9970
它也可以直接拿现成的 OGG 文件来验(参考值取自 libsndfile),并会比对帧数——
自造素材和解码器出自同一份理解,帧数这类差异只有真实文件才逼得出来:
python tools/verify.py song.ogg需要 numpy 与 soundfile。
真实文件覆盖不到的分支得自己造素材。tools/vorbisgen.py 按规范直接拼
比特流,造出的流同时交给本解码器和 libvorbis,两边一致才算读对:
python tools/granule_sweep.py    # 12 组 packet 数 × 尾部裁剪量
python tools/residue_sweep.py    # residue type 0/1 × 单/多声道 × sequence_p
python tools/floor0_sweep.py     # floor 0 的奇/偶阶 × 单/多声道 × 采样率与 Bark 频带数
libvorbis 自 1.0 起只用 floor 1 与 residue type 1/2,官方也没有覆盖全部规范的
测试向量,这几个脚本补的就是这部分。sequence_p 更绕一层:stb_vorbis 与
libvorbis 对它的语义说法不一致,而 stb 那条路径同样没被真实文件走过——
按 libvorbis 实现后 6 组用例相关系数均为 1.000000。
floor 0 连 stb_vorbis 都直接拒收(VORBIS_feature_not_supported),libvorbis
则只在 pre-1.0 的 beta 版里用过它。除了奇数阶与偶数阶要走包络多项式的两个
分支,它还有一处容易读错的地方:floor 0 没有「floor 已用」标志位,幅度字段
本身兼作标志,读出 0 就是本帧没有 floor 数据。9 组用例的相关系数均为 1.000000。
WASM 侧另有两个检查,都跑在 CI 上(见 .github/workflows/ci.yml)。
tools/wasm_contract.py 静态解析二进制,确认导出 decode_ogg_base64 的签名是
String -> String,且除引擎内置外没有任何导入(demo/main.js 用的是空 imports
对象,多一条导入实例化就会失败)。tools/wasm_smoke.mjs 在 Node 里真正跑一遍
解码,再拿产物和命令行解码的输出逐字节比对:
python tools/wasm_contract.py
node tools/wasm_smoke.mjs out.wav
moon run cmd/main --target wasm-gc -- demo/sample.ogg cli.wav
cmp out.wav cli.wav
wasm_smoke.mjs 需要支持 WebAssembly JS String Builtins 的 Node(22 及以上)。
CI 里还会用刚构建出的 wasm 跑一遍、和仓库内 demo/moonvorbis.wasm 的产物比对,
防止 Pages 演示加载的那份产物落后于源码。demo/headless-test.html 是同一件事的
浏览器版本,把 WAV 校验和写进页面,可在浏览器里人工复核:
python -m http.server 8000
# 打开 http://localhost:8000/demo/headless-test.html
随附的 demo/sample.ogg 解出 2ch / 44100Hz / 44100 帧;Node 与命令行两条路径
的产物逐字节相同。
#开发记录
当 52 个测试全绿,却解不出一段正弦波 ——
记录用 stb_vorbis 交叉验证揪出 7 处 Vorbis 规范偏差的过程,以及为什么自造测试
抓不到这类错误。
#限制
- 只做解码,不做编码
#参考与许可
本项目为原创实现,按 Vorbis I specification
(Xiph.Org Foundation)从零开发,未移植任何上游代码,仓库内不含上游源文件。
本项目采用 Apache-2.0 许可证。
开发过程中参考了以下开源项目,仅作为规范的独立读法参照与输出对照,
其源码未并入本项目:
| 项目 | 链接 | 许可证 | 参考范围 |
|---|---|---|---|
| stb_vorbis | https://github.com/nothings/stb/blob/master/stb_vorbis.c | public domain | 作为同一份规范的确定性读法,用于定位 7 处规范理解偏差 |
| libvorbis | https://github.com/xiph/vorbis | BSD-3-Clause | floor 0 合成公式的期望值推算;sequence_p 语义歧义时以其为准;工具脚本的输出对照参考实现 |
tools/ 下的验证脚本调用 libvorbis(经 Python soundfile / libsndfile)作为对照实现,
不复制其代码。
依赖只有下面两条,都是 Apache-2.0,与本项目许可证一致:
| 依赖 | 链接 | 许可证 | 用途 |
|---|---|---|---|
| moonbitlang/core | https://github.com/moonbitlang/core | Apache-2.0 | 缓冲区、base64、UTF-8 解码与数学函数;随 MoonBit 工具链提供 |
| moonbitlang/x | https://github.com/moonbitlang/x | Apache-2.0 | 只有命令行入口用到(moonbitlang/x/fs);解码库本身不依赖 |
仓库内的测试素材与产物均为本项目自行生成,不含任何第三方素材:
| 文件 | 来源 |
|---|---|
| demo/sample.ogg | 按 tools/verify.py 的信号规格生成:左声道 440 Hz、右声道 554 Hz 的立体声正弦波,44.1 kHz、1 秒,无第三方内容 |
| demo/moonvorbis.wasm | 由本仓库源码构建(moon build --target wasm-gc --release) |
| demo/demo.gif | 由 tools/make_demo_gif.py 对 demo/record.html 逐帧截图合成,波形取自真实解码结果 |
tools/vorbisgen.py 及各 sweep 脚本直接按 Vorbis I 规范拼接比特流,所生成的测试流
不派生于任何现有素材。
BitReader
type BitReaderLSB-first 位读取器。
- data : 底层字节序列(只读)
- pos : 当前读取位置,单位是位,从 0 开始计数
BitReader::byte_align
将读取位置对齐到下一个字节边界。
若当前位置恰好落在字节边界上则不做任何事;否则向前跳过当前字节内
剩余的位数(即 8 - (pos mod 8))。
BitReader::read_bits
连续读取 n 位(LSB-first,0 <= n <= 32),返回无符号整数结果。
读取到的第 1 位进入结果的 bit 0(最低位),第 2 位进入 bit 1,依此类推。
BitReader::seek
将读取位置移动到 pos 位处(用于回退或跳跃)。
Codebook
pub struct Codebook {
  dimensions : Int
  entries : Int
  lengths : Array[Int]
  lookup_type : Int
  min_value : Float
  delta_value : Float
  value_bits : Int
  sequence_flag : Int
  multiplicands : Array[Int]
  multiplicands_f : Array[Float]
  huffman : HuffmanTable
}
解析后的 codebook(含码长与 lookup table)。
字段含义:
- lengths : 每个 entry 的码长,hole(sparse 中未使用)用 0 表示;
- lookup_type : 0(无 lookup)、1 或 2;
- multiplicands : lookup table 的量化值(lookup type > 0 时非空)。
Codebook::decode_scalar
标量解码一个码字,返回 entry 索引。
Codebook::decode_vq
VQ 解码:解码一个 entry,把 lookup 值累加到 target[offset..offset+len]。
Codebook::decode_vq_set
VQ 解码:解码若干码字填满 target[offset..offset+len],赋值而非累加。
码字按 dimensions 个分量一组依次摆放,最后一个码字可以只用到一部分分量。
floor 0 用它填充 LSP 系数。
Codebook::decode_vq_step
同 decode_vq,但分量之间隔着 step 个位置摆放,用于 residue type 0 的交织写法。
Decoder
pub struct Decoder {
  info : VorbisInfo
  setup : VorbisSetup
  window0 : Array[Float]
  window1 : Array[Float]
  previous_window : Array[Array[Float]]
  previous_length : Array[Int]
}Floor0
pub struct Floor0 {
  order : Int
  rate : Int
  bark_map_size : Int
  amplitude_bits : Int
  amplitude_offset : Int
  books : Array[Int]
}
floor0 的配置。
Floor0::decode
解析一帧的 floor0 数据,返回 order 个 LSP 系数外加末尾的幅度。
幅度为 0、book 号越界或比特流耗尽时返回 None——这几种情况在参考实现里
都表示「本帧无 floor 数据」,对应声道按静音处理,而不是解码失败。
Floor0::parse
解析 floor0 配置。
codebooks 用于校验 book 编号,并要求被引用的码本带 lookup table
(maptype != 0)且维度大于 0——否则取不出 LSP 系数。
Floor1
pub struct Floor1 {
  partitions : Int
  partition_class_list : Array[Int]
  class_dimensions : Array[Int]
  class_subclasses : Array[Int]
  class_masterbooks : Array[Int]
  subclass_books : Array[Array[Int]]
  multiplier : Int
  rangebits : Int
  x_list : Array[Int]
  sorted_order : Array[Int]
  neighbors : Array[Array[Int]]
}
floor1 的配置与预计算数据。
Floor1::decode
floor1 第一阶段:读 amplitude 与 codebook 值,计算各关键点的 Y 值(finalY)。
Floor1::parse
从 br 的当前位置解析一个 floor1 配置,并预计算 sorted_order 与 neighbors。
HuffmanTable
可复用的 Huffman 解码表。
字段均为排序后(按码字值升序)的码字、码长与对应 entry 索引。
HuffmanTable::build
由码长数组构建解码表。
HuffmanTable::decode
逐位读取并匹配码字,返回对应 entry 索引;未匹配返回错误。
Mapping
mapping 的配置。
- submaps : floor/residue 子流数量;
- magnitude / angle : 耦合声道对(立体声时,主声道与差声道);
- mux : 每个声道使用哪个 submap;
- time_config / floor / residue : 每个 submap 的配置索引。
Mode
pub struct Mode {
  blockflag : Int
  windowtype : Int
  transformtype : Int
  mapping : Int
}
单个 mode 的配置。
OggPage
pub struct OggPage {
  data : Bytes
  offset : Int
  header_type : Int
  granule_position : Int64
  serial_number : UInt
  page_sequence : UInt
  checksum : UInt
  n_segments : Int
  body_len : Int
}
解析后的 OGG 页。
data 保存原始字节序列,offset 是页在其中的起始位置。
segment table 位于 data[offset + 27 .. offset + 27 + n_segments),
body 紧随其后,长度为 body_len。
OggPage::parse
解析从 data[offset] 开始的一个 OGG 页。
成功返回页结构;失败返回错误描述(magic 不符 / 版本不支持 / 数据截断 / CRC 校验失败)。
OggPage::segment_len
返回 segment table 中第 i 项的字节长度(0 <= i < n_segments)。
PacketAssembler
type PacketAssemblerpacket 重组器:跨页累积未完成的 packet。
PacketAssembler::has_partial
当前是否有跨页未完成的 packet(即上一个页以长度为 255 的 segment 结尾)。
PacketAssembler::push_page
处理一个页,返回该页内完成的所有 packet。
跨页未完成的 packet 会累积在内部缓冲中,直到遇到长度 < 255 的 segment 才输出。
调用方应保证页按顺序传入,且页的 CONTINUED 标志与上一个页的未完成状态一致。
Residue
residue 的配置。
- begin / end : 作用的系数范围(end 是开区间上限);
- partition_size : 每个 partition 的系数数量;
- classifications / classbook : 分区分类与对应 codebook;
- cascade : 每个 classification 的残差级联编码描述。
Residue::decode
解码 residue,把残差累加到各声道 target。
n 是半块大小;type 2 的 actual_size 为 n*2,其余为 n。
type 2 且多声道时,VQ 系数按声道交错分配(立体声耦合)。
VorbisComment
Vorbis comment 元数据。
VorbisComment::get
按 key 取第一个匹配的 comment 值,找不到返回 None。
key 按 Vorbis 规范不区分 ASCII 大小写,"title" 与 "TITLE" 等价。
同一个 key 出现多次时(规范允许,例如多个 ARTIST)返回文件中靠前的那个;
需要全部取值时用 get_all。
VorbisComment::get_all
按 key 取全部匹配的 comment 值,保持它们在文件中出现的顺序。
规范允许同一 key 重复出现(如多位 ARTIST),这里不做去重也不做合并。
VorbisComment::parse
解析 Comment header packet,返回 vendor 与 comment 列表。
字符串按 UTF-8 解码(@utf8.decode_lossy),无效字节替换为 U+FFFD,
与 Vorbis comment 的 UTF-8 编码约定相符。
VorbisInfo
pub struct VorbisInfo {
  channels : Int
  sample_rate : Int
  blocksize0 : Int
  blocksize1 : Int
}
Vorbis 流的基础信息。
VorbisInfo::parse
解析 Identification header packet,返回流基础信息。
失败返回错误描述(magic 不符 / 版本不支持 / block size 非法 / 缺 framing 标志 / 数据截断)。
VorbisSetup
完整的 setup 配置。
VorbisSetup::parse
解析 setup header packet,返回完整配置。
channels 是流的声道数(来自 identification header),供 mapping 解析使用。
目前仅支持 floor1(floor0 返回错误)。
VorbisStream
pub struct VorbisStream {
  // private fields
}
从 OGG 页流解码 Vorbis 音频的状态机。
依次消费 identification / comment / setup 三个 header packet,之后的 packet 视为音频帧。
内部状态一律私有:push_page 逐步推进的状态机有先后依赖(header 未就绪就读不了
PCM),字段放开写会让外部绕过这个次序。读取统一走下面的访问器。
VorbisStream::granule_position
已见到的最大 granule position,即合法的 PCM 帧总数;尚未见到时返回 -1。
VorbisStream::is_ready
三个 header 是否已全部解析完成。
VorbisStream::metadata
comment 头里的元数据(TITLE / ARTIST 等);comment 头尚未解析时为 None。
播放器可在 is_ready() 为真后读它来显示曲目信息。
decode_ogg 返回的流一定已解析过 comment 头,除非文件在该头之前就结束了。
VorbisStream::pcm
累计解码出的 PCM 样本(每声道一个 Float 数组,约 [-1,1])。
VorbisStream::push_page
喂入一个 OGG 页,按当前状态解析 header 或解码音频 packet。
VorbisStream::sample_rate
采样率(header 解析完成后可用,否则返回 0)。
VorbisStream::trim_to_granule
把 PCM 裁剪到 granule position 指定的长度。
Vorbis 按块编码,最后一个 packet 往往解出超过原始长度的样本(编码器补的
尾巴)。granule position 才是权威的帧数,多出来的部分必须丢掉。
增量喂页的调用方应在流结束后自行调用一次;decode_ogg 已经代为调用。
decode_ogg
一次性解码整个 OGG 文件字节,返回流(含 PCM 与头信息)。便捷封装。
decode_ogg_base64
fn decode_ogg_base64(ogg_b64 : String) -> String解码 base64 编码的 OGG 数据,返回 base64 编码的 16-bit PCM WAV。
解码失败返回空字符串,调用方据此判断是否成功。
inverse_mdct
Vorbis IMDCT。buffer[0..n2] 为输入频域系数,结果写回 buffer[0..n]。
ogg_crc32
fn ogg_crc32(data : Bytes) -> UInt计算一段完整字节序列的 OGG CRC-32,返回 0 到 0xFFFFFFFF 之间的无符号值。
调用方可将其结果写入 OGG 页头的 22..26 字节(小端)做校验。
ogg_crc32_update
fn ogg_crc32_update(crc : UInt, data : Bytes, start : Int, len : Int) -> UInt增量计算:从已有的 crc 继续处理 data[start .. start + len) 的字节。
用于 OGG 页校验——页内 22..26 字节是 CRC 字段本身,校验时需要把它当作 0
跳过,因此把页头前 22 字节与 26 字节之后的部分分段累加。
parse_modes
从 br 的当前位置解析全部 mode(mode count 在前,后跟每个 mode 的字段)。
校验 windowtype / transformtype 必须为 0(Vorbis 仅支持这一种)。
Install
Download zip纯 MoonBit 实现的 OGG/Vorbis 音频解码器,不依赖任何 C 库或系统编解码器
vorbisoggaudiodecodercodecwasm

 Apache-2.0

 Updated yesterday
 11 downloads
Dependencies
- moonbitlang/x0.5.5