moonseek

    Full-text search platform in pure MoonBit: inverted index, BM25, exact and sloppy phrases, dictionary-free Chinese tokenization, fuzzy search, highlighting, facets, numeric aggregations, HNSW vector search with hybrid fusion, an HTTP service, and a distributed cluster with consistent hashing, scatter-gather on global statistics, write replication, failover, cross-shard aggregations and hybrid retrieval that equal a single node, online rebalancing, replica repair and several coordinators. One snapshot format across native/WASM/JS.

    search
    full-text
    index
    bm25
    chinese
    wasm
    fuzzy
    highlight
    wal
    phrase
    wasm-gc
    hnsw
    vector
    distributed
    aggregation
    consistency
    sharding
    replication
    Download zip
    Version
    0.17.1
    License
    Apache-2.0
    Last updated
    14 hours ago
    Downloads
    109

    #moonseek

    A search platform in pure MoonBit: embeddable library, HTTP service, and horizontally scalable cluster. Inverted index, BM25, dictionary-free Chinese tokenization, fuzzy search, facets, numeric aggregations, HNSW vector search, hybrid fusion — plus an HTTP search service and a distributed coordinator with scatter-gather, globally consistent scoring, replication, failover, online rebalancing, replica repair and cross-shard hybrid retrieval. Runs on native, WebAssembly and JavaScript.

    纯 MoonBit 实现的搜索平台:既是嵌入式库,也是 HTTP 检索服务,还是可水平扩展的集群(一致性哈希、写入复制、在线扩容、副本自愈)。倒排索引、BM25、免词典中文分词、模糊搜索、分面过滤、服务端高亮、WAL 崩溃恢复,支持 native / WASM / JS 三端。

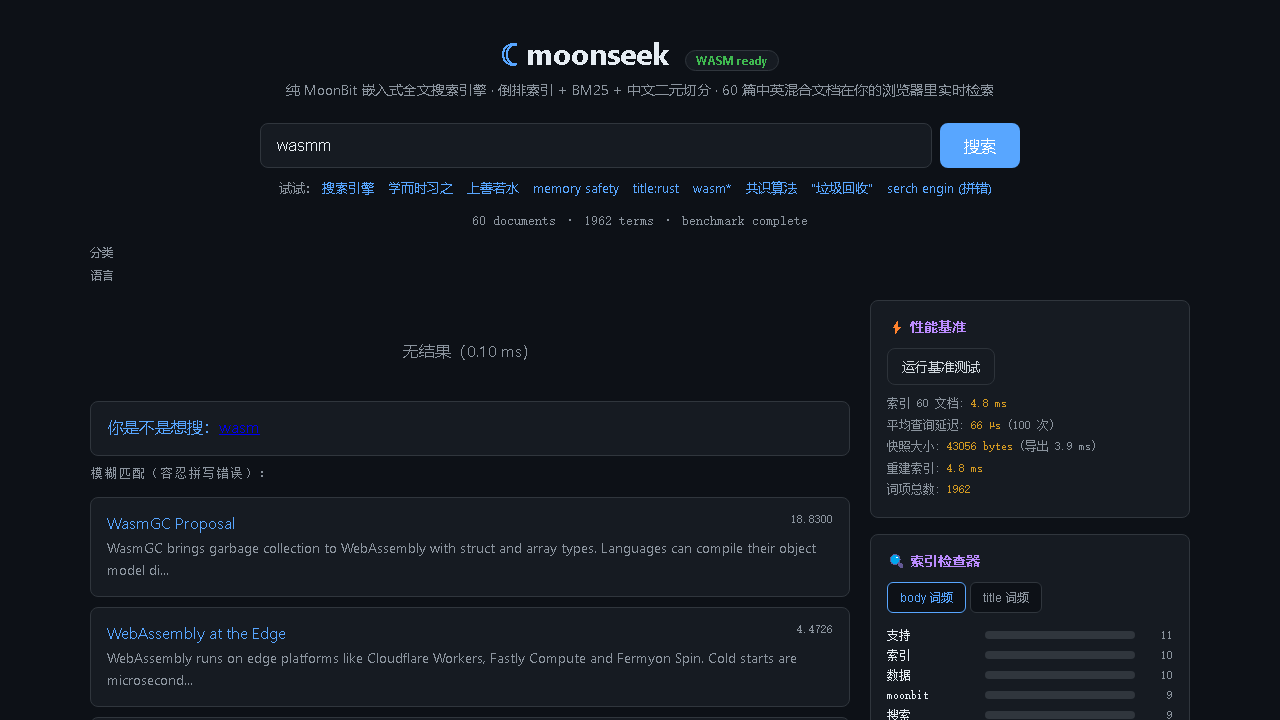
    ▶ Live demo: naiwaniubi.github.io/moonseek — searches all 3,698 packages on mooncakes.io in your browser. No server, no network requests after load. Also: drop your own files in and index them live, and read the measured quality/ablation report.

    CI License mooncakes tests

    moonseek demo

    #Why moonseek

    MoonBit's ecosystem has HTTP servers, crypto and database drivers — but no tantivy/Lucene-class embedded search engine. moonseek fills that gap with a single dependency-light library that works everywhere MoonBit compiles, including inside the browser via WasmGC.

    #Features

    • Inverted index with per-field weights (e.g. title ×3, body ×1)
    • BM25 ranking with configurable k1 / b
    • Chinese + English tokenization: Latin words with stop-word removal; CJK overlapping bigrams (Lucene CJKAnalyzer strategy) — no dictionary needed
    • Rich query syntax: term, "exact phrase", "a b"~3 (sloppy phrase: up to 3 tokens between terms), AND / OR / NOT, field:term, prefix*, parentheses, implicit AND
    • Fuzzy search: Levenshtein / Damerau-Levenshtein edit distance with early-exit bounded DP; BK-tree for sub-linear lookup (13–1780× faster than linear scan on a 24k-term vocabulary)
    • Did-you-mean: frequency-weighted spelling correction (suggest)
    • Faceted search: exact-match facet fields, AND/OR filters, per-facet value counts, offset pagination (search_faceted)
    • Ranking control: configurable sort — score, id, or a numeric field, in either direction, over HTTP as sort=num:year&order=desc and in the library as search_sorted; cursor pagination (search_after); per-term BM25 breakdown (explain). A cross-shard numeric sort is exact: the shards ship the key
    • Server-side highlighting: highlight / snippet with HTML escaping, CJK-aware codepoint spans, overlap merging, densest-window extraction
    • Stored fields: original texts kept in the index, retrievable via get_document / get_field, survive snapshots
    • Segmented index: immutable segments + tiered merge policy + cross-segment search with latest-version-wins (SegmentedIndex)
    • Write-ahead log: CRC-framed entries, torn-tail recovery, durable add + atomic checkpoint + crash-safe reopen (native)
    • Crash-safe persistence: versioned snapshot + CRC-32 checksum; atomic save (temp file → fsync → rename); torn/corrupt files are rejected, never silently loaded
    • Portable: pure MoonBit core (no FFI in the engine); native file store via moonbitlang/async; browser export via WasmGC + js-string builtins. One snapshot format, two backends: an index built by the native binary loads byte-for-byte into the browser's wasm-gc build
    • Measured quality, not just latency: NDCG@10 / MRR@10 / Recall@20 over 3,698 real packages with a 6-way ablation (docs/quality.md)
    • HTTP service: a REST search API (docs/api.md) with bulk ingest, facets, aggregations, highlighting, explain, suggest and vector queries. The console in console/ drives it
    • Durable service: --data-dir journals every accepted write (CRC-framed, data fsync) before applying it and checkpoints atomically, so a restart replays text, facets, numbers, vectors and deletions exactly. One fsync per bulk batch keeps durable ingest within ~1.2–1.3× of in-memory, and concurrent single-document writes share a flush through group commit — 1.9× at 8 writers, 3.4× at 32 over one-fsync-per-request. tools/test-durability.sh and tools/test-durability-concurrent.sh restart the process to prove it
    • Distributed cluster: one binary is a node, a shard or a coordinator. Consistent hashing (a fourth shard moves 24% of the corpus, not 75%), write routing with replication to every group member, cross-shard facets, aggregations, sorts and hybrid retrieval that equal a single node, globally consistent scoring (?dfs=true reproduced a single node's ranking exactly, 8/8 queries, zero score difference), POST /_rebalance to grow without a reindex (the plan predicted 762 moves and the executor made 762, ending at exactly the predicted distribution), POST /_repair to bring a member that missed writes back in line, replica failover, and partial answers that name the shards that failed (docs/cluster.md)
    • Vector search: pure-MoonBit HNSW with measured recall against brute force (0.996@ef=32, 0.999@ef=64 on 1,000 random 32-d points), plus hybrid BM25 × kNN fusion by reciprocal rank
    • Numeric aggregations: terms, stats, histogram and percentiles over a result set, with numeric doc values alongside facets
    • Document lifecycle: add, replace (same id), delete

    #How it works

    flowchart LR T[text] --> A[Analyzer<br/>Latin words + CJK bigrams] A --> I[Inverted index<br/>field → term → postings<br/>doc, freq, positions] Q[query string] --> P[Lexer → parser<br/>term / phrase / prefix / AND OR NOT] P --> E[Evaluator<br/>ascending doc arrays<br/>merge-based set ops] I --> E E --> K[Top-K selection<br/>score desc, id asc] K --> H[hits] I --> S[Snapshot MSK3<br/>CRC-32 frame] I --> W[WAL<br/>torn-tail recovery] I --> F[Facets<br/>filter + aggregation] B[Browser<br/>WasmGC + js-string] -.-> I

    #Three ways to run it

    1. Embedded — the library, as above. moon add NaIWaniubi/moonseek.

    2. As a service — one process, an HTTP search API and the console:

    moon build server --target native --release ./_build/native/release/build/server/server.exe --addr 127.0.0.1:7700 --assets console curl -X POST localhost:7700/index/bulk --data-binary @docs.jsonl curl "localhost:7700/search?q=parser&facets=license"

    Add --data-dir ./data to make it survive a restart: every accepted write is journaled with a data fsync before it is applied, and POST /_checkpoint (or every 10,000 records) snapshots atomically and truncates the journal. Text, facets, numeric columns, vectors and deletions all come back on replay — tools/test-durability.sh restarts the process to prove it. Without the flag the server is in-memory only and says so (/_checkpoint returns 400).

    3. As a cluster — three shards and a coordinator that owns no data:

    for k in 0 1 2; do ./server.exe --addr 127.0.0.1:$((7801+k)) --shard-port 127.0.0.1:$((7901+k)) & done ./server.exe --addr 127.0.0.1:7805 --shards "127.0.0.1:7901,127.0.0.1:7902,127.0.0.1:7903" # ?dfs=true makes the ranking identical to a single node holding the whole corpus curl "localhost:7805/search?q=parser&dfs=true"

    4. The whole thing in one command — a replicated cluster, the corpus loaded through the coordinator, and the console served:

    tools/demo.sh # starts it and prints the URLs tools/demo-story.sh # or: the full story as a script (see docs/demo-video.md)

    tools/demo-story.sh walks search → dfs → hybrid retrieval → grow 3→4 groups without a reindex → repair a diverged member → kill a primary (failover) → kill its replica (honest degradation). It is the thing to screen-record, and docs/demo-video.md is the shot list with narration.

    Nine end-to-end scripts run in CI, each its own job so a failure is attributable: tools/test-cluster.sh (dfs ranking, placement agreement, the ring's reshuffle, distributed aggregations, sorted queries, distributed hybrid retrieval, failover, two coordinators), tools/test-replication.sh (a replicated write survives the loss of its primary), tools/test-rebalance.sh (grow 3 shards to 4 without reindexing), tools/test-repair.sh (a member that missed writes is brought back), tools/test-repair-edge.sh (an empty primary still removes a replica's ghost, and an unreachable member is named rather than skipped), tools/test-shard-restart.sh (a pooled shard connection survives its shard restarting), tools/test-durability.sh (writes, deletes, vectors and numbers survive a restart), tools/test-durability-concurrent.sh (no acknowledged write is lost across 16 concurrent writers and 25 forced checkpoints), and tools/soak-cluster.mjs (writes, queries, checkpoints and a mid-run shard restart sustained together, then every acknowledged write checked against every member of its group). To grow a running cluster:

    ./server.exe --addr 127.0.0.1:7805 --shards "…:7920,…:7921,…:7922,…:7923" # after adding the new shard curl -X POST "localhost:7805/_rebalance?from=3" curl -X POST "localhost:7805/_repair" # after a member comes back

    tools/check-cluster.mjs runs the cluster-vs-single-node comparison and prints the identity and latency tables in docs/cluster.md. tools/bench-cluster.mjs measures what fan-out costs: it starts K shards, one single node on the same corpus and one coordinator, and interleaves the samples so the machine's drifting load cannot bias one arm.

    3 shards, 3,000 docssingle nodecoordinatorratio
    mean query p50 (6 shapes)——1.13×
    one forwarded write——1.31×
    2,000 writes, 3 groups × 2 members320 docs/s254 docs/s1.26×, all fully acknowledged

    Ask a coordinator where a document lives with GET /_placement?id=…, and what a grow-out would cost with GET /_plan?shards=4.

    #Quick start

    let index = @moonseek.Index::new([
    { name: "title", weight: 3.0 },
    { name: "body", weight: 1.0 },
    ])

    index.add({
    id: "doc1",
    fields: [
    ("title", "全文搜索引擎"),
    ("body", "倒排索引是搜索引擎的核心,BM25 负责排序。"),
    ],
    })
    index.add({
    id: "doc2",
    fields: [("title", "MoonBit"), ("body", "A fast language for WebAssembly")],
    })

    let hits = index.search("搜索引擎") // [{ id: "doc1", score: … }]
    let hits2 = index.search("title:moonbit") // field-scoped
    let hits3 = index.search("\"memory safety\" OR wasm*") // phrase + prefix

    // Persist (native)
    index.save("index.msk")
    let restored = @moonseek.Index::load("index.msk")

    // Or portable bytes (works on every backend)
    let image : Bytes = index.to_bytes()
    let restored2 = @moonseek.Index::from_bytes(image)

    #CLI

    moon run cmd/main -- index ./docs --index index.msk # index .txt/.md files moon run cmd/main -- search "搜索引擎" --index index.msk moon run cmd/main -- search "title:rust" --limit 5 moon run cmd/main -- info --index index.msk

    #Browser demo

    A complete search engine running inside your browser — no server, no network:

    moon build --target wasm-gc cp _build/wasm-gc/debug/build/web/web.wasm demo/web.wasm cd demo && python -m http.server 8000 # open http://localhost:8000 (Chrome / Edge with WasmGC + js-string builtins)

    The demo does three things, all in the browser:

    1. Searches the real registry. Every one of the 3,698 packages published on mooncakes.io (22,837 versions) is indexed — package names, author-written keywords, descriptions, and dependency edges. The index is built by the native binary into a 1.37 MB MSK3 snapshot and loaded by the wasm-gc build, which is the strongest evidence that the format is portable. Loading takes ~200 ms; the median query over a 12-query mix is 0.20 ms.
    2. Indexes your own files. Drag in .txt / .md / .json / .csv / .log files (or paste text) and they are parsed, tokenized and searchable immediately, with the whole index persistable to IndexedDB as one snapshot blob and reloadable without re-parsing.
    3. Shows its own quality. A live benchmark measures query-latency percentiles and the latency-vs-index-size curve in your browser, next to the ablation table from tools/eval: the same corpus and queries under six scoring configurations, so you can see which mechanism is worth how much NDCG.

    Results use server-side highlighting (the WASM engine produces escaped HTML with CJK-aware <mark> spans), misspelled queries get did-you-mean suggestions and fuzzy fallback, and every hit can expand into its BM25 score breakdown.

    #Performance

    moon bench --target native --release, 1000 synthetic documents (~80 tokens each), AMD Ryzen 7 7435H:

    Small corpus (moon bench, 1000 synthetic docs, mean +/- sigma):

    OperationTime
    Index 1000 docs (with stored fields)85.8 ms +/- 6.2
    Term query (top-10)262 us +/- 12
    Phrase query (top-10)1.01 ms +/- 0.24
    Snapshot save + load45.3 ms +/- 2.7

    Stress test (bench/stress, 20,000 docs / 8.57 MB text / 23,782 terms, release). Build is the median of 4 timed runs; queries are p50 of 200 samples, limit=10:

    OperationTime
    Index build2.73 s -> 7,320 docs/s (median of 4)
    Selective term (df 285)0.06 ms
    Field-scoped term (df 732)0.13 ms
    Saturated term (df 4,021)0.36 ms with block-max (see below)
    Chinese bigram (df 4,113)0.37 ms
    Boolean query3.02 ms
    Exact phrase6.25 ms -> 0.29 ms (rarest-term walk, ~24x)
    Sloppy phrase "a b"~39.80 ms -> 1.04 ms (~9x)
    Prefix query seg*2.34 ms -> 0.44 ms (one term -> block-max)
    Facet filter + aggregation (3,055 matches)14.0 ms
    Fuzzy lookup, 23.8k termslinear 37-46 ms -> BK-tree 0.07-2.7 ms (17-491x)
    Snapshot 17.6 MB: serialize / load0.68 s / 0.75 s

    Block-max WAND on a bounded query that is a single term, a conjunction, or a disjunction with a wide document-frequency spread: the doc-sorted postings are walked in blocks of 16 and, once the top-k is full, a block is skipped when its highest reachable score is below the k-th best. A conjunction additionally drives on its shortest term, so a saturated term is never enumerated. On the corpus above this skips 70–74% of the postings: a single saturated term drops from ~2.0 ms to 0.92 ms (2.2×) and search AND engine from ~4.3 ms to 2.7 ms. A disjunction takes the walk only when a dense operand sets the threshold and a much rarer one creates the gap — search OR <4 rare terms> is then 29% faster and skips 75% of the postings — because otherwise the plain merge wins; the gate (or_walk_pays), its measurements and the tests pinning both sides are in docs/benchmark.md. Everywhere the result is bit-for-bit the full scan, because a block is skipped only on a strict inequality (a tie is still scored, so it can still win the id tiebreak) and the tests assert the equality, including a corpus with a huge tie group on the cut.

    Browser (WasmGC, the 3,698-package registry snapshot): 206 KB binary, snapshot load ~200 ms, median query 0.20 ms, p90 0.2-0.3 ms, snapshot export ~200-315 ms.

    Full methodology, per-shape ranges and an explicit list of what is not measured: docs/benchmark.md.

    #Architecture

    token.mbt Analyzer: Latin words + CJK bigrams, positions index.mbt Inverted index, field stats, BM25, stored fields query.mbt Lexer → recursive-descent parser → evaluator fuzzy.mbt Levenshtein/Damerau distance, fuzzy search suggest.mbt Frequency-weighted did-you-mean highlight.mbt Server-side highlight/spans/snippet (codepoint offsets) facet.mbt Facet values, filters, aggregations, pagination bktree.mbt BK-tree for sub-linear fuzzy lookup explain.mbt BM25 breakdown, sort orders, cursor pagination segment.mbt SegmentedIndex: immutable segments + tiered merge wal.mbt CRC-framed write-ahead log (portable byte layer) wal_native.mbt Durable add/checkpoint/crash recovery (native) codec.mbt Varint / UTF-8 / double / CRC-32 primitives snapshot.mbt MSK3 format: versioned payload + checksum + stored fields + facets store.mbt Native atomic file persistence (async/fs) web/ Browser exports (#export_name, js-string builtins) cmd/main/ CLI: index / search / info examples/ Runnable examples (basic, persistence) demo/ Single-page browser demo (60 docs, benchmarks, inspector)

    See docs/architecture.md for design details and the snapshot format specification.

    #Testing

    moon test # 299 tests (native) moon test --target wasm-gc moon test --target js moon bench --release # benchmarks moon coverage analyze # coverage report moon run bench/stress --target native --release # 20k-doc stress benchmark

    Tests cover tokenization, boolean/phrase/prefix/fuzzy queries, BM25 ordering, spelling correction, highlighting spans and HTML escaping, segment merge correctness, WAL torn-tail recovery, snapshot roundtrips, corruption/truncation detection, crash-safe file persistence, and quickcheck properties (roundtrip, varint, positions, delete exclusion).

    #Roadmap

    #License

    Apache-2.0. Built for the MoonBit open-source ecosystem.

    CodecError

    pub(all) suberror CodecError {
    UnexpectedEof
    VarintOverflow
    InvalidUtf8
    BadMagic
    BadVersion(Int)
    CrcMismatch(UInt, UInt)
    } derive(Eq,
    Debug
    )

    Decoding errors (truncated or malformed data).
    impl Show for CodecError

    CodecError::equal

    fn CodecError::equal(CodecError, CodecError) -> Bool

    CodecError::not_equal

    fn CodecError::not_equal(x : CodecError, y : CodecError) -> Bool

    CodecError::output

    fn CodecError::output(self : CodecError, logger : &Logger) -> Unit

    Human-readable one-line description, used by the WAL segment header diagnostics and by Show interpolation in user-facing messages.

    CodecError::to_string

    fn CodecError::to_string(self : CodecError) -> String

    Human-readable one-line description, used by the WAL segment header diagnostics and by Show interpolation in user-facing messages.

    QueryError

    pub(all) suberror QueryError {
    EmptyQuery
    UnterminatedPhrase
    UnexpectedToken(String)
    UnknownField(String)
    } derive(Eq,
    Debug
    )

    Query syntax errors.
    impl Show for QueryError

    QueryError::equal

    fn QueryError::equal(QueryError, QueryError) -> Bool

    QueryError::not_equal

    fn QueryError::not_equal(x : QueryError, y : QueryError) -> Bool

    QueryError::output

    fn QueryError::output(self : QueryError, logger : &Logger) -> Unit

    QueryError::to_string

    fn QueryError::to_string(self : QueryError) -> String

    StoreError

    pub(all) suberror StoreError {
    IoError(String)
    CorruptIndex(String)
    } derive(Eq,
    Debug
    )

    Errors from the store layer.
    impl Show for StoreError

    StoreError::equal

    fn StoreError::equal(StoreError, StoreError) -> Bool

    StoreError::not_equal

    fn StoreError::not_equal(x : StoreError, y : StoreError) -> Bool

    StoreError::output

    fn StoreError::output(self : StoreError, logger : &Logger) -> Unit

    StoreError::to_string

    fn StoreError::to_string(self : StoreError) -> String

    AggResult

    pub(all) struct AggResult {
    field : String
    kind : String
    buckets : Array[(String, Double)]
    stats : StatSummary?
    percentiles : Array[(Double, Double)]
    } derive(Eq,
    Debug
    )

    The result of one aggregation. Exactly one of buckets / stats / percentiles is populated, according to the spec that produced it; the unused fields are empty rather than absent so serialization stays uniform.

    AggResult::equal

    fn AggResult::equal(AggResult, AggResult) -> Bool

    AggResult::not_equal

    fn AggResult::not_equal(x : AggResult, y : AggResult) -> Bool

    AggResult::to_json

    AggSpec

    pub(all) enum AggSpec {
    TermsAgg(String, Int)
    StatsAgg(String)
    HistogramAgg(String, Double)
    PercentilesAgg(String, Array[Double])
    } derive(Eq,
    Debug
    )

    One aggregation request.

    AggSpec::equal

    fn AggSpec::equal(AggSpec, AggSpec) -> Bool

    AggSpec::not_equal

    fn AggSpec::not_equal(x : AggSpec, y : AggSpec) -> Bool

    AggSpec::to_repr

    Analyzer

    pub(all) struct Analyzer {
    lowercase : Bool
    remove_stop_words : Bool
    cjk_bigram : Bool
    } derive(Eq,
    Debug
    )

    Text analyzer configuration.
    impl Default for Analyzer

    Analyzer::analyze

    fn Analyzer::analyze(self : Analyzer, text : String) -> Array[Token]

    Analyze text into a stream of tokens. Latin words are split on non-word characters; CJK runs become overlapping bigrams (single characters are emitted for runs of length 1).

    Analyzer::default

    fn Analyzer::default() -> Analyzer

    Analyzer::equal

    fn Analyzer::equal(Analyzer, Analyzer) -> Bool

    Analyzer::not_equal

    fn Analyzer::not_equal(x : Analyzer, y : Analyzer) -> Bool

    Analyzer::to_repr

    BkTree

    pub struct BkTree {
    // private fields
    }

    A BK-tree over a dictionary of terms.

    BkTree::from_terms

    fn BkTree::from_terms(terms : Array[String]) -> BkTree

    Build a BK-tree from an array of terms.

    BkTree::insert

    fn BkTree::insert(self : BkTree, term : String) -> Unit

    Insert a term. Duplicates are ignored.

    BkTree::len

    fn BkTree::len(self : BkTree) -> Int

    Number of terms in the tree.

    BkTree::new

    fn BkTree::new() -> BkTree

    BkTree::search

    fn BkTree::search(self : BkTree, query : String, max_distance? : Int) -> Array[FuzzyMatch]

    Find all terms within max_distance edits of query. Results are sorted by (distance, term).

    BlockMaxResult

    pub(all) struct BlockMaxResult {
    hits : Array[Hit]
    scored : Int
    skipped : Int
    } derive(Eq,
    Debug
    )

    A block-max top-k run, with the work it did: postings scored and postings skipped because their whole block could not reach the threshold. The counters exist so the optimization is measured, not assumed.

    BlockMaxResult::equal

    BlockMaxResult::not_equal

    fn BlockMaxResult::not_equal(x : BlockMaxResult, y : BlockMaxResult) -> Bool

    Bm25Params

    pub(all) struct Bm25Params {
    k1 : Double
    b : Double
    } derive(Eq,
    Debug
    )

    BM25 parameters (Robertson/Sparck Jones defaults).

    Bm25Params::default

    fn Bm25Params::default() -> Bm25Params

    Bm25Params::equal

    fn Bm25Params::equal(Bm25Params, Bm25Params) -> Bool

    Bm25Params::not_equal

    fn Bm25Params::not_equal(x : Bm25Params, y : Bm25Params) -> Bool

    ByteWriter

    pub struct ByteWriter {
    // private fields
    }

    ByteWriter: an append-only byte buffer with amortized O(1) pushes. Array[Byte].push re-allocates as the array grows; indexing into a preallocated FixedArray-backed buffer makes snapshot serialization substantially faster (17 MB image: 2.4 s → sub-second).

    ByteWriter::append

    fn ByteWriter::append(self : ByteWriter, other : ByteWriter) -> Unit

    Append another writer's contents.

    ByteWriter::length

    fn ByteWriter::length(self : ByteWriter) -> Int

    ByteWriter::new

    fn ByteWriter::new(capacity? : Int) -> ByteWriter

    ByteWriter::push

    fn ByteWriter::push(self : ByteWriter, b : Byte) -> Unit

    ByteWriter::push_bytes

    fn ByteWriter::push_bytes(self : ByteWriter, data : Bytes) -> Unit

    ByteWriter::to_bytes

    fn ByteWriter::to_bytes(self : ByteWriter) -> Bytes

    Snapshot the written region as an immutable Bytes.

    ByteWriter::write_double

    fn ByteWriter::write_double(self : ByteWriter, value : Double) -> Unit

    ByteWriter::write_string

    fn ByteWriter::write_string(self : ByteWriter, s : String) -> Unit

    ByteWriter::write_u32_le

    fn ByteWriter::write_u32_le(self : ByteWriter, value : UInt) -> Unit

    ByteWriter::write_varint

    fn ByteWriter::write_varint(self : ByteWriter, value : Int) -> Unit

    Varint (LEB128), string, double and u32 writers matching codec.mbt.

    DocScores

    pub struct DocScores {
    docs : Array[Int]
    scores : Array[Double]
    }

    Evaluation result: ascending docs with their accumulated scores.

    DocScores::diff

    fn DocScores::diff(a : DocScores, b : DocScores) -> DocScores

    Difference: docs of a not present in b (sorted set), scores kept.

    DocScores::empty

    fn DocScores::empty() -> DocScores

    DocScores::from_pairs

    fn DocScores::from_pairs(pairs : Array[(Int, Double)]) -> DocScores

    Build from unsorted (doc, score) pairs: sorts by doc and sums duplicates.

    DocScores::inter

    fn DocScores::inter(a : DocScores, b : DocScores) -> DocScores

    Intersection: docs in both, scores summed.

    DocScores::is_empty

    fn DocScores::is_empty(self : DocScores) -> Bool

    DocScores::length

    fn DocScores::length(self : DocScores) -> Int

    DocScores::push

    fn DocScores::push(self : DocScores, doc : Int, score : Double) -> Unit

    Append a posting whose doc is strictly greater than the last one.

    DocScores::union

    fn DocScores::union(a : DocScores, b : DocScores) -> DocScores

    Union: every doc of either, scores summed on collision.

    Document

    pub(all) struct Document {
    id : String
    fields : Array[(String, String)]
    } derive(Eq,
    Debug
    )

    A document to be indexed. id is caller-assigned and must be unique within the index; re-adding an existing id replaces the old document.

    Document::equal

    fn Document::equal(Document, Document) -> Bool

    Document::not_equal

    fn Document::not_equal(x : Document, y : Document) -> Bool

    Document::to_repr

    Explanation

    pub(all) struct Explanation {
    id : String
    total_score : Double
    details : Array[ScoreDetail]
    } derive(Eq,
    Debug
    )

    Full explanation for one hit.

    Explanation::equal

    fn Explanation::equal(Explanation, Explanation) -> Bool

    Explanation::not_equal

    fn Explanation::not_equal(x : Explanation, y : Explanation) -> Bool

    Explanation::to_json

    ExternalStats

    pub(all) struct ExternalStats {
    n : Int
    df :
    HashMap
    [(String, String), Int]
    avgdl :
    HashMap
    [String, Double]
    } derive(Eq,
    Debug
    )

    Corpus-wide statistics, as a coordinator computes them.

    Only the three numbers BM25 actually reads are carried: the live document count, the per-(field, term) document frequency, and the per-field average length. Anything else would be a statistic the scoring path does not use.

    ExternalStats::equal

    ExternalStats::new

    fn ExternalStats::new(n : Int, df? : Array[((String, String), Int)], avgdl? : Array[(String, Double)]) -> ExternalStats

    ExternalStats::not_equal

    fn ExternalStats::not_equal(x : ExternalStats, y : ExternalStats) -> Bool

    FacetCount

    pub(all) struct FacetCount {
    value : String
    count : Int
    } derive(Eq,
    Debug
    )

    One facet value with its document count in a result set.

    FacetCount::equal

    fn FacetCount::equal(FacetCount, FacetCount) -> Bool

    FacetCount::not_equal

    fn FacetCount::not_equal(x : FacetCount, y : FacetCount) -> Bool

    FacetCount::to_json

    FacetFilter

    pub(all) struct FacetFilter {
    field : String
    values : Array[String]
    } derive(Eq,
    Debug
    )

    A facet filter: field name + required values (OR within, AND across fields).

    FacetFilter::equal

    fn FacetFilter::equal(FacetFilter, FacetFilter) -> Bool

    FacetFilter::not_equal

    fn FacetFilter::not_equal(x : FacetFilter, y : FacetFilter) -> Bool

    FacetFilter::to_json

    FacetedResult

    pub(all) struct FacetedResult {
    hits : Array[Hit]
    total : Int
    facets : Array[(String, Array[FacetCount])]
    } derive(Eq,
    Debug
    )

    Search result with optional facet aggregations.

    FacetedResult::equal

    FacetedResult::not_equal

    fn FacetedResult::not_equal(x : FacetedResult, y : FacetedResult) -> Bool

    FacetedResult::to_json

    FieldSchema

    pub(all) struct FieldSchema {
    name : String
    weight : Double
    } derive(Eq,
    Debug
    )

    Field schema: name + scoring weight (e.g. title=3.0, body=1.0).

    FieldSchema::equal

    fn FieldSchema::equal(FieldSchema, FieldSchema) -> Bool

    FieldSchema::not_equal

    fn FieldSchema::not_equal(x : FieldSchema, y : FieldSchema) -> Bool

    FieldStats

    type FieldStats

    Per-field statistics needed by BM25.

    Fusion

    pub(all) enum Fusion {
    Rrf
    Weighted(Double)
    } derive(Eq,
    Debug
    )

    How two rankings are combined.

    Fusion::equal

    fn Fusion::equal(Fusion, Fusion) -> Bool

    Fusion::not_equal

    fn Fusion::not_equal(x : Fusion, y : Fusion) -> Bool

    Fusion::to_repr

    FuzzyMatch

    pub(all) struct FuzzyMatch {
    term : String
    distance : Int
    } derive(Eq,
    Debug
    )

    One dictionary term within the fuzzy distance bound.

    FuzzyMatch::equal

    fn FuzzyMatch::equal(FuzzyMatch, FuzzyMatch) -> Bool

    FuzzyMatch::not_equal

    fn FuzzyMatch::not_equal(x : FuzzyMatch, y : FuzzyMatch) -> Bool

    HighlightSpan

    pub struct HighlightSpan {
    start : Int
    end : Int
    } derive(Eq,
    Debug
    )

    A half-open character range [start, end) in a stored field's original text. Offsets count Unicode codepoints: neither bytes nor UTF-16 code units.

    HighlightSpan::equal

    HighlightSpan::not_equal

    fn HighlightSpan::not_equal(x : HighlightSpan, y : HighlightSpan) -> Bool

    Hit

    pub(all) struct Hit {
    id : String
    score : Double
    } derive(Eq,
    Debug
    )

    One search hit.

    Hit::equal

    fn Hit::equal(Hit, Hit) -> Bool

    Hit::not_equal

    fn Hit::not_equal(x : Hit, y : Hit) -> Bool

    Hit::to_json

    fn Hit::to_json(self : Hit) ->
    Json

    JSON serialization for result types (public API parity with web/api.mbt).

    Hit::to_repr

    HnswGraph

    pub struct HnswGraph {
    layer0 : Array[Array[Int]]
    upper : Array[Array[Array[Int]]]
    entry : Int
    top_layer : Int
    len : Int
    m : Int
    m0 : Int
    ef_construction : Int
    dim : Int
    // private fields
    }

    A HNSW graph over the documents of one vector field.

    Layers are flat adjacency lists. Layer 0 allows up to m0 neighbours per node; upper layers up to m. entry is where search starts, top_layer the highest non-empty layer.

    HnswGraph::max_layer

    fn HnswGraph::max_layer(self : HnswGraph) -> Int

    Highest populated layer (0 for a graph of a single node).

    HnswGraph::search

    fn HnswGraph::search(self : HnswGraph, points : HnswPoints, query : Array[Double], k : Int, ef? : Int) -> Array[(Int, Double)]

    kNN search over the graph. Returns (doc, distance) pairs, closest first.

    ef is the layer-0 beam width: larger means better recall and more work. It is raised to at least k, since a beam narrower than the result set cannot return k distinct results.

    HnswGraph::size

    fn HnswGraph::size(self : HnswGraph) -> Int

    Number of nodes in the graph.

    HnswPoints

    type HnswPoints

    Vectors of one field, laid out for the distance loop.

    Two choices matter here. Points are stored in one flat buffer with a dim-wide stride rather than as an array of arrays, so a distance computation walks contiguous memory instead of chasing a pointer per vector. And lookup is by internal doc number arithmetic rather than a hash map probe: the graph search computes millions of distances, and a hash lookup per distance dominated construction time when this was a HashMap[Int32, Array[Double]].

    HybridHit

    pub(all) struct HybridHit {
    id : String
    score : Double
    lexical_rank : Int
    vector_rank : Int
    } derive(Eq,
    Debug
    )

    One fused hit from hybrid retrieval.

    HybridHit::equal

    fn HybridHit::equal(HybridHit, HybridHit) -> Bool

    HybridHit::not_equal

    fn HybridHit::not_equal(x : HybridHit, y : HybridHit) -> Bool

    Index

    pub struct Index {
    schema : Array[FieldSchema]
    analyzer : Analyzer
    bm25 : Bm25Params
    // private fields
    }

    An in-memory inverted index over a fixed field schema.

    All mutable state is private: callers reach it only through the accessor methods (schema/analyzer/bm25/doc_count/search/...), never by holding a shared reference to the internal tables. Exposing the HashMaps would let any caller corrupt index invariants and hard-code the storage layout into the package ABI.

    Index::add

    fn Index::add(self : Index, doc : Document) -> Unit

    Add or replace a document. Unknown field names abort.

    Index::agg_values

    fn Index::agg_values(self : Index, query : String, field : String, filters? : Array[(String, Array[String])]) -> Array[Double] raise QueryError

    The raw numeric values of field over the documents a query matched and the filters admitted — the same result set aggregate runs over.

    This exists for exactly one reason: percentiles cannot be merged from per-shard summaries. Averaging shard medians is a different number from the median of the union, and not a small difference — with two shards it can be off by half the spread. A distributed percentile therefore has to ship the values themselves, which is why this is a separate call that a client opts into rather than part of the ordinary aggregation path.

    Index::aggregate

    fn Index::aggregate(self : Index, query : String, specs : Array[AggSpec], filters? : Array[(String, Array[String])]) -> Array[AggResult] raise QueryError

    Run aggregation specs over the documents that a query matched and that pass the given facet filters. This is deliberately the same result set the caller returned hits from: aggregating over a different set is the classic way a search UI ends up lying about its own facets.

    filters is a list of (field, allowed values) pairs; a document must match at least one value in each pair (OR within, AND across).

    Index::all_live_scores

    fn Index::all_live_scores(self : Index, excluded : DocScores, keep : (Int) -> Bool) -> DocScores

    Docs absent from both the index's deleted set and excluded, scored 0.0. Used for MatchAll and MatchField (pure selectors, no BM25 term).

    Index::analyzer

    fn Index::analyzer(self : Index) -> Analyzer

    The analyzer this index was created with.

    Index::and_terms_topk

    fn Index::and_terms_topk(self : Index, terms : Array[(String, String?)], limit : Int) -> BlockMaxResult

    Top-k for a conjunction of terms (a b, a AND b, with each term possibly field-scoped), by a leapfrog walk over the shortest term's postings plus the same block-max pruning the single-term path uses.

    Two things make it cheap and exact:

    • The shortest list drives. Only documents of the most selective term can be matches, so the walk visits them and asks the other terms whether they occur at that document. A saturated term is never enumerated.
    • A block whose bound cannot reach the threshold is skipped. The bound is the sum, over the terms, of each term's own block maximum — a document in the block must be in every term, so its total score cannot exceed that sum. The test is strict, so a document that only ties is still scored and can still win the id tiebreak.

    Scores are summed in the query's term order, which is the order the exact evaluator's nested intersections sum in, so the result is bit-for-bit the full evaluation.

    Index::bk_tree

    fn Index::bk_tree(self : Index, field? : String?) -> BkTree

    Build a BK-tree from the index's vocabulary (all fields or one field). The tree is cached inside the index and reused across calls until the next add; building one per query costs more than a linear scan for vocabularies under ~100k terms.

    Index::bm25

    fn Index::bm25(self : Index) -> Bm25Params

    The BM25 parameters this index was created with (for diagnostics).

    Index::collect_hits

    fn Index::collect_hits(self : Index, scored : DocScores, limit : Int) -> Array[Hit]

    Materialize a result set into Hits ordered by (score desc, id asc) and truncated to limit (0 = everything).

    With a positive limit this is a bounded selection: a candidate is only turned into a Hit (document-id lookup included) once it beats the current worst of the top set, so a saturated query does not pay for n string lookups.

    Index::count

    fn Index::count(self : Index, query : String) -> Int raise QueryError

    Number of live documents matching a query, without materializing hits.

    search(query, limit=0) answers the same question but builds and sorts every Hit first. A shard reporting its match count needs the number and nothing else, and paying for the ranking made the cluster's per-query cost an order of magnitude larger than the search itself.

    Index::delete

    fn Index::delete(self : Index, id : String) -> Bool

    Delete a document by external id. Returns true if it existed.

    Index::doc_count

    fn Index::doc_count(self : Index) -> Int

    Number of live documents.

    Index::doc_freq

    fn Index::doc_freq(self : Index, field : String, term : String) -> Int

    Document frequency of a term in a field (0 if absent).

    Index::doc_id

    fn Index::doc_id(self : Index, num : Int) -> String?

    Look up the external id of an internal doc number.

    Index::explain

    fn Index::explain(self : Index, query : String, id : String) -> Explanation? raise QueryError

    Explain the score of a query for a specific document. Returns None if the document doesn't match or doesn't exist.

    Index::field_doc_count

    fn Index::field_doc_count(self : Index, field : String) -> Int

    Number of live documents that carry field (public view of the same count avg_field_length divides by).

    Index::field_length_total

    fn Index::field_length_total(self : Index, field : String) -> Int

    Sum of analyzed token counts over every live document that carries field. The index already maintains this as part of per-field statistics, so a cluster coordinator can ask for it in O(1). Recomputing it by re-analyzing every document made the two-phase distributed query an order of magnitude slower than the search it was gathering statistics for.

    Index::field_lengths

    fn Index::field_lengths(self : Index, field : String) -> Array[Int]

    Dense per-field token counts indexed by internal doc number (0 when the document has no content in that field). Cached until the next mutation. Replaces the per-posting HashMap probe on the BM25 scoring path.

    Index::from_bytes

    fn Index::from_bytes(data : Bytes) -> Index raise CodecError

    Restore an index from a byte image. Raises on bad magic, unknown version, truncation, or checksum mismatch.
    fn Index::fuzzy_search(self : Index, term : String, max_distance? : Int, limit? : Int) -> Array[Hit] raise QueryError

    Fuzzy search: expand term to dictionary terms within max_distance edits, evaluate each as a term query, and merge per-document scores by taking the maximum (a document matching several variants is not boosted for the repetition). Results are sorted by descending score, ties by id, and capped at limit (0 = unlimited), mirroring Index::search. Declared raise QueryError for API symmetry with Index::search; the current implementation never raises.

    Index::fuzzy_terms

    fn Index::fuzzy_terms(self : Index, term : String, max_distance? : Int, field? : String?) -> Array[FuzzyMatch]

    Find dictionary terms within max_distance edits of term, sorted by (distance, term). Distance is Damerau-Levenshtein (adjacent transpositions count as one edit, matching common typing errors). max_distance is clamped to [0, 2]. field restricts the vocabulary (None = all fields). Terms whose length differs by more than max_distance are skipped before any distance computation, so cost stays linear in vocabulary size.

    Index::fuzzy_terms_fast

    fn Index::fuzzy_terms_fast(self : Index, term : String, max_distance? : Int, field? : String?) -> Array[FuzzyMatch]

    Fast fuzzy term lookup using a BK-tree. Same semantics as fuzzy_terms but sub-linear for small distances on large vocabularies.

    Index::get_document

    fn Index::get_document(self : Index, id : String) -> Document?

    Retrieve the stored original document by external id. Returns None if the id is unknown or the document was deleted.

    Index::get_facets

    fn Index::get_facets(self : Index, id : String) -> Array[(String, Array[String])]

    Get facet values for a document.

    Index::get_field

    fn Index::get_field(self : Index, id : String, field : String) -> String?

    Retrieve one stored field's original text.

    Index::get_vector

    fn Index::get_vector(self : Index, id : String, field : String) -> Array[Double]?

    The vector attached to a document for a field, or None. The counterpart to set_vector.

    It exists for migration. A rebalance that moved a document's text but not its vector would leave the destination answering text queries and silently missing vector ones — a search that returns fewer hits than before, with no error anywhere.

    Index::has_external_stats

    fn Index::has_external_stats(self : Index) -> Bool

    Whether external statistics are currently installed (diagnostics).

    Index::highlight

    fn Index::highlight(self : Index, id : String, field : String, query : String, pre_tag? : String, post_tag? : String) -> String raise QueryError

    Return the stored field text with pre_tag/post_tag around every highlight span. The source text is HTML-escaped (& < > " '); the tags themselves are not escaped. With no matches the escaped original is returned unchanged.

    Index::highlight_spans

    fn Index::highlight_spans(self : Index, id : String, field : String, query : String) -> Array[HighlightSpan] raise QueryError

    Compute highlight spans of query over the stored original text of one field. Latin terms match whole analyzed tokens (case handling follows the index analyzer); CJK bigram terms map back to their exact source ranges; phrases highlight the full adjacent run; prefixes highlight every whole token starting with the prefix. Overlapping ranges are merged and the result is sorted by start. Raises UnknownField for an unknown/deleted document or a field the document does not carry; query syntax errors propagate from parse_query.

    Index::hnsw_graph

    fn Index::hnsw_graph(self : Index, field : String) -> HnswGraph

    The HNSW graph for a field, built on first use and cached until a mutation.
    fn Index::hybrid_search(self : Index, query : String, vector : Array[Double], vector_field : String, limit? : Int, candidate_pool? : Int, fusion? : Fusion, ef? : Int, exact? : Bool) -> Array[HybridHit] raise QueryError

    Hybrid retrieval: BM25 and vector kNN, fused.

    This is the retrieval layer a RAG pipeline wants. BM25 catches exact terms, identifiers and rare words; the vector side catches paraphrases; RRF merges them without requiring the two score scales to be comparable.

    Index::is_deleted

    fn Index::is_deleted(self : Index, num : Int) -> Bool

    True when the internal doc number is a tombstone.

    Index::knn

    fn Index::knn(self : Index, field : String, query : Array[Double], k : Int, ef? : Int) -> Array[(String, Double)]

    Graph kNN, with similarity (1 - distance) so a higher score is better — matching how a BM25 score reads to a caller.

    Index::knn_exact

    fn Index::knn_exact(self : Index, field : String, query : Array[Double], k : Int) -> Array[(Int, Double)]

    Brute-force kNN: exact, O(n) per query. This is the reference the graph is measured against, and the fallback for tiny collections where building a graph costs more than it saves.

    Index::knn_exact_ids

    fn Index::knn_exact_ids(self : Index, field : String, query : Array[Double], k : Int) -> Array[(String, Double)]

    Brute-force kNN keyed by document id, with similarity (1 - distance) so a higher score is better and the ranking reads like knn. Ties break by id, which makes the order deterministic — the property a distributed comparison against a single node needs, since it cannot tolerate two runs of the same query disagreeing on a tie.

    Index::knn_recall

    fn Index::knn_recall(self : Index, field : String, queries : Array[Array[Double]], k : Int, ef? : Int) -> Double

    Recall@k of the graph search against brute force over a query set. This is the number that says whether an approximate index is usable: an approximate index with unmeasured recall is a guess.

    Index::load

    async fn Index::load(path : String) -> Index raise StoreError

    Load an index from path. Raises if the file is missing or corrupt.

    Index::load_or_create

    async fn Index::load_or_create(path : String, schema : Array[FieldSchema]) -> Index raise StoreError

    Load an index from path, or create a fresh one if the file does not exist. A corrupt file is still an error (never silently discarded). Existence is judged with @fs.exists, not @fs.can_read: a file that exists but is unreadable (permissions, exclusive lock, AV scan) must surface as an error, because silently creating a fresh in-memory index would let the next save() atomically overwrite and destroy it.

    Index::new

    fn Index::new(schema : Array[FieldSchema], analyzer? : Analyzer, bm25? : Bm25Params) -> Index

    Create an empty index. Panics on duplicate field names.

    Index::num_column

    fn Index::num_column(self : Index, field : String) -> Array[Double]

    Dense numeric column for a field: index i holds the value of internal doc number i, or NaN when the document has no value for the field. Cached until the next mutation. NaN is the sentinel rather than 0.0 because 0.0 is a legitimate value and treating "absent" as zero would corrupt every average.

    Index::num_of

    fn Index::num_of(self : Index, id : String, field : String) -> Double?

    Numeric value of one field for one document, or None.

    Index::numeric_fields

    fn Index::numeric_fields(self : Index) -> Array[String]

    Field names that carry at least one numeric value.

    Index::or_terms_topk

    fn Index::or_terms_topk(self : Index, terms : Array[(String, String?)], limit : Int) -> BlockMaxResult

    Top-k for a disjunction of terms (a OR b), by the same block-max idea as the conjunction: walk the union in document order and skip a whole doc block when the sum of the terms' block maxima cannot reach the current k-th best.

    A document's score is the sum of the terms that occur in it, accumulated in the query's term order — the order the exact evaluator's nested unions add in — so the result is bit-for-bit the full evaluation. Terms that match nothing are dropped (an empty operand of a union contributes nothing).

    search routes here through or_walk_pays, which is what keeps the walk off the shapes where it loses; the numbers behind that gate are on that function.

    Index::or_walk_pays

    fn Index::or_walk_pays(self : Index, terms : Array[(String, String?)]) -> Bool

    Whether a disjunction should take the block-max walk instead of the exact merge. A block is skipped when the terms' summed block maxima cannot reach the threshold, which needs two things at once:

    • a dense operand — so the threshold is set high by a term with postings in every block, giving the sparse terms' blocks something to fall below;
    • a much rarer operand — so most blocks contain none of it and the summed bound really does drop below the threshold.

    With only the first, nothing can be skipped; with only the second, the union is short enough that the plain merge is already the cheapest thing to do, and the walk's per-document bookkeeping — it peeks, scores and advances every cursor once per candidate document — is pure loss. So the gate asks for a densest operand holding at least a tenth of the documents and an operand at least ten times rarer than it.

    Measured on 20k documents, --release, min of 200 interleaved samples (bench/stress/main.mbt): one dense term (df 4021) with four rare ones (df 285) is ~30% faster through the walk, one dense with eight rare is a wash, two or three comparably dense operands are a wash to 20% slower, and eight rare terms with no dense operand are ~1.7× slower — the five rows the tests pin, three routed to the walk and two left to the merge. It is a performance choice only: the two paths return identical results (the tests assert that), so the gate can never change an answer.

    Public because search consults it and tooling (the stress bench) reports which path a disjunction takes.

    Index::postings_of

    fn Index::postings_of(self : Index, field : String, term : String) -> Array[Posting]

    Postings of a term in a field (empty if absent).

    Index::save

    async fn Index::save(self : Index, path : String) -> Unit raise StoreError

    Save the index to path atomically (write temp + fsync + rename).

    Index::schema

    fn Index::schema(self : Index) -> Array[FieldSchema]

    The field schema (names and weights), in declaration order.

    Index::search

    fn Index::search(self : Index, query : String, limit? : Int) -> Array[Hit] raise QueryError

    Search the index. limit caps the number of hits (0 = unlimited). Results are sorted by descending score, ties broken by document id.

    Evaluation produces ascending (doc, score) arrays and selection is a bounded top-K walk over them, so a query never materializes a doc -> score map and only the hits that enter the top set are turned into Hit values.

    Index::search_after

    fn Index::search_after(self : Index, query : String, after_score~ : Double, after_id~ : String, limit? : Int) -> Array[Hit] raise QueryError

    Cursor-based pagination: return hits after the given (score, id) cursor. More stable than offset pagination when documents are added/removed between pages. Pass the last hit's score and id from the previous page.

    Index::search_exact

    fn Index::search_exact(self : Index, query : String, limit? : Int) -> Array[Hit] raise QueryError

    The unbounded evaluation of search, without the block-max top-k shortcut. search returns the same hits; this exists so a caller can force the full-scan path — the benchmark compares the two, and the tests check that the shortcut is indistinguishable from it.

    Index::search_faceted

    fn Index::search_faceted(self : Index, query : String, options? : SearchOptions) -> FacetedResult raise QueryError

    Faceted search: query + filters + aggregations + pagination.

    Index::search_sorted

    fn Index::search_sorted(self : Index, query : String, limit? : Int, sort? : SortOrder) -> Array[Hit] raise QueryError

    Search with configurable sort order.

    Index::set_external_stats

    fn Index::set_external_stats(self : Index, stats : ExternalStats?) -> Unit

    Install corpus-wide statistics for the next searches, or clear them with None. A coordinator sets them, runs the query, and clears them; leaving them installed would silently mis-score a later local query.

    Index::set_facets

    fn Index::set_facets(self : Index, id : String, facets : Array[(String, Array[String])]) -> Bool

    Set facet values for a document (replaces any previous values). Returns false (and does nothing) when the document does not exist or is deleted; true when the values were stored. Unknown fields are created on the fly (facets don't need schema declaration).

    Index::set_num

    fn Index::set_num(self : Index, id : String, field : String, value : Double) -> Bool

    Attach a numeric value to a document (replaces any previous value for the same field). Returns false when the document does not exist or is deleted. Unlike text fields, numeric fields need no schema declaration — the same choice facets make, for the same reason: a search service rarely knows its numeric facets at compile time.

    Index::set_vector

    fn Index::set_vector(self : Index, id : String, field : String, vector : Array[Double]) -> Bool

    Index a vector for a document. A field's dimensionality is fixed by its first vector; a later vector of a different length is rejected rather than truncated, because truncation yields distances that look plausible and are wrong.

    Index::slot_count

    fn Index::slot_count(self : Index) -> Int

    Number of internal document slots, including deleted ones. A stable upper bound for iterating doc_id over the index's history.

    Index::snippet

    fn Index::snippet(self : Index, id : String, field : String, query : String, max_chars? : Int, pre_tag? : String, post_tag? : String) -> String raise QueryError

    Extract a snippet of at most max_chars source characters: the window containing the most highlight spans (ties: earliest window), with the same tags and HTML escaping as highlight. Ellipses "…" mark truncation on either side. With no highlights the first max_chars characters are returned. max_chars <= 0 yields an empty string.

    Index::suggest

    fn Index::suggest(self : Index, query : String, max_distance? : Int) -> String?

    Did-you-mean spelling correction. For each bare word in the query that is absent from the dictionary but has a close match, return the query with the first such word corrected; all other text is preserved verbatim. Field-scoped terms (field:term), quoted phrases, operators (AND/OR/NOT), prefixes (foo*), and parentheses are left untouched. Candidates are ranked by document frequency so common words win over rare ones. Returns None when nothing is correctable. max_distance is clamped to [0, 2].

    Index::term_count

    fn Index::term_count(self : Index) -> Int

    Number of distinct terms across all fields.

    Index::term_topk_blockmax

    fn Index::term_topk_blockmax(self : Index, field : String?, term : String, limit : Int) -> BlockMaxResult

    Top-k for a single term by Block-Max WAND (Ding & Suel): walk the postings in doc order, and skip a whole doc block when the highest score any posting in it could reach is below the current k-th best.

    The bound is per block of BLOCK_SIZE consecutive doc numbers, taken from that block's maximum term frequency and minimum document length — the score rises with frequency and falls with length, so the pair dominates every posting in the block. A block is skipped only when its bound is strictly below the threshold, so a document that merely ties with the current k-th best is still scored and can still win the id tiebreak: the result is identical to scoring every posting, not merely close.

    field restricts the term to one field (the common case); with None the term is summed across fields, and the per-block bound is the sum of the fields' bounds, which still dominates a document's total.

    Index::terms_of

    fn Index::terms_of(self : Index, field : String) -> Array[String]

    All terms in a field, sorted in lexicographic (dictionary) order.

    Note: String::compare is SHORTLEX in MoonBit (compares lengths first), which scatters terms sharing a prefix across the array. Prefix queries need true lexicographic order to be contiguous, so this uses lexical_compare explicitly.

    The sorted list is cached and reused until the next add; callers must treat the returned array as read-only.

    Index::to_bytes

    fn Index::to_bytes(self : Index) -> Bytes

    Serialize the index to a portable byte image. Uses ByteWriter (preallocated, amortized growth) instead of Array[Byte] push: serializing the 17 MB stress image drops from ~2.4 s to ~0.7 s.

    Index::tokens_in

    fn Index::tokens_in(self : Index, text : String) -> Int

    Token count of a string under this index's analyzer. Exposed because a cluster coordinator needs field lengths to compute a global avgdl, and it must count tokens the same way the index did.

    Index::vector_count

    fn Index::vector_count(self : Index, field : String) -> Int

    Number of live indexed vectors in a field.

    Index::vector_dim

    fn Index::vector_dim(self : Index, field : String) -> Int

    Dimensionality of a vector field, or 0 when nothing has been indexed.

    Index::vector_fields

    fn Index::vector_fields(self : Index) -> Array[String]

    Field names that carry at least one vector, sorted. The vector counterpart of numeric_fields, and what migration iterates so it cannot miss a field it did not know about.

    JournalDoc

    pub(all) struct JournalDoc {
    id : String
    fields : Array[(String, String)]
    facets : Array[(String, Array[String])]
    nums : Array[(String, Double)]
    vectors : Array[(String, Array[Double])]
    } derive(Eq,
    Debug
    )

    One accepted write, in full.

    JournalDoc::equal

    fn JournalDoc::equal(JournalDoc, JournalDoc) -> Bool

    JournalDoc::not_equal

    fn JournalDoc::not_equal(x : JournalDoc, y : JournalDoc) -> Bool

    JournalEntry

    pub(all) enum JournalEntry {
    Put(JournalDoc)
    Remove(String)
    } derive(Eq,
    Debug
    )

    One durable server mutation.

    JournalEntry::equal

    JournalEntry::not_equal

    fn JournalEntry::not_equal(x : JournalEntry, y : JournalEntry) -> Bool

    Posting

    pub(all) struct Posting {
    doc : Int
    freq : Int
    positions : Array[Int]
    } derive(Eq,
    Debug
    )

    One posting: which document, how many times, and where.

    Posting::equal

    fn Posting::equal(Posting, Posting) -> Bool

    Posting::not_equal

    fn Posting::not_equal(x : Posting, y : Posting) -> Bool

    Posting::to_repr

    QToken

    Tokenize a query string into raw pieces: words, quoted phrases, operators (AND OR NOT), parentheses, and field prefixes.

    QToken::equal

    fn QToken::equal(QToken, QToken) -> Bool

    QToken::not_equal

    fn QToken::not_equal(x : QToken, y : QToken) -> Bool

    QToken::to_repr

    Query

    pub(all) enum Query {
    Term(String, String?)
    Phrase(Array[String], String?, Int)
    Prefix(String, String?)
    And(Query, Query)
    Or(Query, Query)
    Not(Query, Query)
    MatchAll
    MatchField(String)
    } derive(Eq,
    Debug
    )

    A parsed query node.

    Query::equal

    fn Query::equal(Query, Query) -> Bool

    Query::not_equal

    fn Query::not_equal(x : Query, y : Query) -> Bool

    Query::to_repr

    Reader

    pub struct Reader {
    data : Bytes
    pos : Int
    }

    Cursor over a byte slice for decoding.

    Reader::new

    fn Reader::new(data : Bytes) -> Reader

    Reader::read_byte

    fn Reader::read_byte(self : Reader) -> Byte raise CodecError

    Reader::read_double

    fn Reader::read_double(self : Reader) -> Double raise CodecError

    Reader::read_string

    fn Reader::read_string(self : Reader) -> String raise CodecError

    Reader::read_u32_le

    fn Reader::read_u32_le(self : Reader) -> UInt raise CodecError

    Reader::read_varint

    fn Reader::read_varint(self : Reader) -> Int raise CodecError

    Reader::remaining

    fn Reader::remaining(self : Reader) -> Int

    ScoreDetail

    pub(all) struct ScoreDetail {
    field : String
    term : String
    tf : Int
    df : Int
    idf : Double
    norm : Double
    score : Double
    } derive(Eq,
    Debug
    )

    One term's contribution to a document's score.

    ScoreDetail::equal

    fn ScoreDetail::equal(ScoreDetail, ScoreDetail) -> Bool

    ScoreDetail::not_equal

    fn ScoreDetail::not_equal(x : ScoreDetail, y : ScoreDetail) -> Bool

    ScoreDetail::to_json

    SearchOptions

    pub(all) struct SearchOptions {
    limit : Int
    offset : Int
    filters : Array[FacetFilter]
    facet_fields : Array[String]
    } derive(Eq,
    Debug
    )

    Search options extending the basic query with facets and pagination.

    SearchOptions::default

    fn SearchOptions::default() -> SearchOptions

    SearchOptions::equal

    SearchOptions::not_equal

    fn SearchOptions::not_equal(x : SearchOptions, y : SearchOptions) -> Bool

    SearchOptions::to_json

    SegmentedIndex

    pub struct SegmentedIndex {
    schema : Array[FieldSchema]
    analyzer : Analyzer
    bm25 : Bm25Params
    segments : Array[Index]
    active : Index
    segment_max_docs : Int
    }

    A multi-segment full-text index.

    SegmentedIndex::add

    fn SegmentedIndex::add(self : SegmentedIndex, doc : Document) -> Unit

    Add or replace a document in the active segment. Freezes the active segment once it reaches segment_max_docs live documents. Re-adding an id tombstones its older versions in frozen segments so that position-based readers (get_document) agree with search's newest-wins resolution even before a merge compacts the stack.

    SegmentedIndex::add_durable

    async fn SegmentedIndex::add_durable(self : SegmentedIndex, dir : String, doc : Document) -> Unit raise StoreError

    Append an Add entry to dir/wal.log (fsync) and then apply it in memory. dir must be the same directory passed to open_or_create.

    SegmentedIndex::checkpoint

    async fn SegmentedIndex::checkpoint(self : SegmentedIndex, dir : String) -> Unit raise StoreError

    Atomically persist the full index state and clear the WAL. Write temp + fsync + rename, then truncate the log.

    SegmentedIndex::delete

    fn SegmentedIndex::delete(self : SegmentedIndex, id : String) -> Bool

    Mark a document deleted in every segment (all versions of the id). Returns true if the id existed, matching Index::delete semantics (an already-deleted id still "exists" as a tombstone).

    SegmentedIndex::delete_durable

    async fn SegmentedIndex::delete_durable(self : SegmentedIndex, dir : String, id : String) -> Bool raise StoreError

    Append a Delete entry to dir/wal.log (fsync) and then apply it in memory. Returns true if the id existed (same semantics as delete).

    SegmentedIndex::doc_count

    fn SegmentedIndex::doc_count(self : SegmentedIndex) -> Int

    Number of distinct live documents (newest version per id wins).

    SegmentedIndex::flush

    fn SegmentedIndex::flush(self : SegmentedIndex) -> Unit

    Freeze the active segment into the immutable stack (no-op if empty).

    SegmentedIndex::from_bytes

    fn SegmentedIndex::from_bytes(data : Bytes) -> SegmentedIndex raise CodecError

    Restore a segmented index from a byte image. Raises on bad magic, unknown version, truncation, or checksum mismatch.

    SegmentedIndex::get_document

    fn SegmentedIndex::get_document(self : SegmentedIndex, id : String) -> Document?

    Retrieve the newest live version of a document by external id.

    SegmentedIndex::get_field

    fn SegmentedIndex::get_field(self : SegmentedIndex, id : String, field : String) -> String?

    Retrieve one stored field's text from the newest live version.

    SegmentedIndex::merge

    fn SegmentedIndex::merge(self : SegmentedIndex, max_segments? : Int) -> Unit

    Tiered merge policy. Segments are bucketed by size class (floor(log2(live docs))). While the total segment count exceeds max_segments, the most populated tier is collapsed into a single rebuilt segment; ties go to the smallest tier so tiny segments are swept up first (classic tiered/"log-structured" behavior). The active segment participates so a merge also folds in recent writes. Rebuild replays the newest live version of every document through Index::add, which drops deleted docs and reassigns doc numbers.

    SegmentedIndex::new

    fn SegmentedIndex::new(schema : Array[FieldSchema], segment_max_docs? : Int) -> SegmentedIndex

    Create an empty segmented index. segment_max_docs is clamped to >= 1.

    SegmentedIndex::open_or_create

    async fn SegmentedIndex::open_or_create(dir : String, schema : Array[FieldSchema]) -> SegmentedIndex raise StoreError

    Open the index stored in dir, or create a fresh one. Replays the WAL on top of the last checkpoint. The directory is created if missing.

    SegmentedIndex::search

    fn SegmentedIndex::search(self : SegmentedIndex, query : String, limit? : Int) -> Array[Hit] raise QueryError

    Search every segment and merge the hits.

    Newest-wins resolution: each segment is queried normally, then every hit is resolved against the newest live version of its id. A hit for a deleted id is dropped; a hit for a stale version is re-scored by evaluating the same parsed query against a one-document index built from the newest version. This guarantees update semantics identical to a single index: terms that only existed in the old version stop matching, and scores always reflect the newest content.

    Scoring across segments: each segment computes BM25 with its own local IDF/avgdl, so raw scores are NOT directly comparable. We normalize per segment by dividing each hit score by that segment's maximum score for the query (max-score normalization to [0, 1]). This is the standard federated-search approximation: it preserves within-segment ranking exactly and makes cross-segment ordering depend on relative, not absolute, relevance. Ties (including all MatchAll hits, which score 1.0 everywhere) are broken by document id, ascending, for determinism.

    SegmentedIndex::segment_count

    fn SegmentedIndex::segment_count(self : SegmentedIndex) -> Int

    Number of segments: frozen (immutable) ones plus the active segment if it holds any documents. An empty active segment is not counted.

    SegmentedIndex::to_bytes

    fn SegmentedIndex::to_bytes(self : SegmentedIndex) -> Bytes

    Serialize: magic "MSKS" | payload | crc32(payload) u32le. Payload: version | segment_max_docs | schema | analyzer/bm25 config | immutable segment count | each segment as length-prefixed MSK3 image | active segment as length-prefixed MSK3 image.

    SortOrder

    pub(all) enum SortOrder {
    ScoreDesc
    ScoreAsc
    IdAsc
    IdDesc
    NumAsc(String)
    NumDesc(String)
    } derive(Eq,
    Debug
    )

    Sort order for search results.

    NumAsc/NumDesc order by a numeric document value. Documents with no value for the field sort last in both directions: a missing value is not a small number, and putting the value-less documents first in a descending sort would make "newest first" begin with the ones that have no date.

    SortOrder::equal

    fn SortOrder::equal(SortOrder, SortOrder) -> Bool

    SortOrder::not_equal

    fn SortOrder::not_equal(x : SortOrder, y : SortOrder) -> Bool

    StatSummary

    pub(all) struct StatSummary {
    count : Int
    min : Double
    max : Double
    avg : Double
    sum : Double
    } derive(Eq,
    Debug
    )

    Descriptive statistics over one numeric field of a result set.

    StatSummary::equal

    fn StatSummary::equal(StatSummary, StatSummary) -> Bool

    StatSummary::not_equal

    fn StatSummary::not_equal(x : StatSummary, y : StatSummary) -> Bool

    StatSummary::to_json

    JSON serialization (public API parity with the other result types).

    Token

    pub(all) struct Token {
    term : String
    position : Int
    } derive(Eq,
    Debug
    )

    A token emitted by the analyzer: the normalized term plus its position in the token stream (used for phrase queries).

    Token::equal

    fn Token::equal(Token, Token) -> Bool

    Token::not_equal

    fn Token::not_equal(x : Token, y : Token) -> Bool

    Token::to_repr

    WalEntry

    pub(all) enum WalEntry {
    Add(Document)
    Delete(String)
    } derive(Eq,
    Debug
    )

    One durable mutation.

    WalEntry::equal

    fn WalEntry::equal(WalEntry, WalEntry) -> Bool

    WalEntry::not_equal

    fn WalEntry::not_equal(x : WalEntry, y : WalEntry) -> Bool

    WalEntry::to_repr

    BLOCK_SIZE

    let BLOCK_SIZE : Int

    Documents per block for the block-max top-k walk. 64 is the usual choice: large enough that one extra scored posting costs little, small enough that a block's maximum stays tight and skip decisions land often.

    build_hnsw

    fn build_hnsw(vectors : Array[(Int, Array[Double])], dim : Int, m? : Int, ef_construction? : Int, seed? : UInt64) -> HnswGraph

    Build the graph over a vector field. vectors maps internal doc number to its vector and must contain live documents only.

    Construction follows ascending doc number, so the graph is a pure function of the data plus the seed. That is what lets the recall tests assert exact numbers rather than ranges.

    compare_numeric

    fn compare_numeric(index : Index, field : String, left : String, right : String, forward~ : Bool) -> Int

    Order two documents by a numeric value, with the value-less ones last in whichever direction the sort runs.

    Returns a comparison in the requested order (so the caller can pass it straight to sort_by), which is why the sign is applied inside.

    cosine_distance

    fn cosine_distance(a : Array[Double], b : Array[Double]) -> Double

    Cosine distance in [0, 2] = 1 - cosine similarity. Callers are expected to pass normalized vectors; normalizing here as well means an unnormalized vector degrades ranking slightly instead of letting its magnitude dominate.

    Public because it is the metric the index actually ranks by, and a caller comparing its own vectors to the index's should not have to re-derive it. HnswPoints::dist computes the same expression over the flat buffer, in the same order, so the two agree bit for bit.

    crc32

    fn crc32(data : Bytes) -> UInt

    CRC-32 (IEEE) of a byte slice.

    damerau_levenshtein

    fn damerau_levenshtein(a : String, b : String) -> Int

    Damerau-Levenshtein distance (optimal string alignment variant): like Levenshtein, but an adjacent transposition costs one edit. Rolling 3-row DP: O(m*n) time, O(min(m,n)) space. The OSA restriction (no substring edited more than once) matches the common "typo distance" use case.

    damerau_levenshtein_bounded

    fn damerau_levenshtein_bounded(a : String, b : String, bound : Int) -> Int

    Damerau-Levenshtein distance with an early exit: returns bound + 1 as soon as no cell in the current row can lead to a distance <= bound. This is what makes fuzzy matching over large vocabularies fast — the full-matrix version allocated m*n cells per candidate.

    explain_terms

    fn explain_terms(index : Index, query : Query) -> Array[String]

    Terms the evaluator actually scores for a query, matching eval: Phrase contributes its first term only (phrase frequency is folded in), Prefix expands to the matching dictionary terms, Not contributes only its left branch.

    fuse_rankings

    fn fuse_rankings(lexical : Array[(String, Double)], semantic : Array[(String, Double)], limit? : Int, fusion? : Fusion) -> Array[HybridHit]

    Fuse an already-ranked lexical list with an already-ranked semantic list. Both are (id, score), best first. The single-node hybrid path and the coordinator both call this — the coordinator builds the same two global lists from per-shard answers — so there is exactly one fusion implementation and the two cannot drift apart.

    is_missing_number

    fn is_missing_number(v : Double) -> Bool

    True when a numeric column cell holds no value. Uses the self-comparison trick: NaN is the only double that is not equal to itself, and writing it this way cannot be accidentally rewritten by a constant folder.

    journal_append

    async fn journal_append(dir : String, entry : JournalEntry) -> Unit raise StoreError

    Append one record to dir/journal.log with a data fsync. Returns only after the record is durable, so a caller may then apply it in memory.

    journal_append_bytes

    async fn journal_append_bytes(dir : String, bytes : Array[Byte]) -> Unit raise StoreError

    Append pre-encoded journal fragments in one write with one data fsync.

    The caller builds the bytes with journal_frame, one fragment per record, so several requests that arrived at the same time can share the flush. The framing is unchanged: every fragment carries its own magic, length and CRC, so a batch torn by a crash replays its complete prefix and nothing more.

    journal_append_entry

    fn journal_append_entry(buf : Array[Byte], entry : JournalEntry) -> Unit

    Encode one entry as a framed record (type byte + payload + crc32). The caller supplies the buffer so a batch append can encode several entries into one write.

    journal_append_many

    async fn journal_append_many(dir : String, entries : Array[JournalEntry]) -> Unit raise StoreError

    Append several records in one write with one data fsync. Each record keeps its own CRC frame, so a batch torn by a crash still replays its complete prefix — batching does not weaken the guarantee, it only shares the fsync. That matters for bulk ingest: one fsync per document costs about 2.6× the throughput of one per batch on this machine.

    journal_checkpoint

    async fn journal_checkpoint(dir : String, index : Index) -> Int raise StoreError

    Write the index to dir/index.msk atomically and truncate the journal. A crash before the rename leaves the old snapshot plus the whole journal (replayed on open); a crash after the rename but before the truncation replays already-checkpointed records, which is idempotent because a Put replaces by id and Remove is a tombstone. An empty journal is left alone rather than recreated, so the next append still writes its header.

    Returns the snapshot size in bytes. Serializing the index is the expensive half of a checkpoint, so the caller gets the size from the write it already paid for instead of serializing the whole index a second time just to report a number.

    journal_decode

    fn journal_decode(data : Bytes) -> Array[JournalEntry] raise CodecError

    Decode a journal image, replaying every complete entry. Stops silently at a torn or corrupt tail; raises only if the leading header is not a journal.

    journal_encode

    fn journal_encode(entries : Array[JournalEntry]) -> Bytes

    Encode entries as a complete journal image (header + frames).

    journal_frame

    fn journal_frame(entry : JournalEntry) -> Bytes

    One entry as a self-contained journal fragment: the magic header followed by the framed record.

    Concatenating fragments yields a valid journal image — journal_decode skips a repeated header — which is what lets several independently arriving writes share a single write and a single fsync instead of each paying for its own. The fragment is complete on its own, so a batch torn by a crash still replays its whole prefix.

    journal_has_snapshot

    async fn journal_has_snapshot(dir : String) -> Bool raise StoreError

    True when dir holds a checkpoint, so a caller can decide whether to create an empty index or load the stored one.

    journal_load_snapshot

    async fn journal_load_snapshot(dir : String) -> Index raise StoreError

    The stored snapshot, for replay to start from. Raises when it is absent or corrupt — a corrupt snapshot must never be silently replaced by an empty index, which the next checkpoint would make permanent.

    journal_replay

    async fn journal_replay(dir : String) -> Array[JournalEntry] raise StoreError

    Every record in dir/journal.log, in order. A missing journal is an empty log, not an error. A torn tail replays only the complete prefix; a file that is not a journal at all raises.

    levenshtein

    fn levenshtein(a : String, b : String) -> Int

    Levenshtein edit distance between two strings, counting insertions, deletions and substitutions. Operates on Unicode code points (Chars), so CJK and astral-plane characters each count as one character. Classic DP with a single row: O(m*n) time, O(min(m,n)) space.

    parse_query

    fn parse_query(input : String, analyzer? : Analyzer, fields? : Array[String]) -> Query raise QueryError

    Parse a query string against the index's schema.

    percentiles_of

    fn percentiles_of(values : Array[Double], ps : Array[Double]) -> Array[(Double, Double)]

    Percentiles of an arbitrary value set, with the same interpolation the single-node aggregation uses.

    Exposed so a coordinator can compute a percentile over the union of the shards' values and get the number a single-node index of the same corpus would have produced. It takes the values unsorted and sorts a copy, so the caller's array is not disturbed.

    query_terms

    fn query_terms(query : Query) -> Array[String]

    Collect the highlightable terms of a query AST: every Term and Phrase word, plus the prefix itself for Prefix nodes. The right branch of Not and MatchAll contribute nothing (only positive matches are highlighted). Results are deduplicated in first-occurrence order.

    scoring_terms

    fn scoring_terms(index : Index, query : Query) -> Array[(String, String)]?

    The (field, term) pairs a query would score, for a cluster coordinator that has to gather corpus-wide df before scoring.

    Shape mirrors the evaluator: a bare term expands to one pair per declared field, field:term to one, and a phrase to its first term, because that is the term the evaluator scores it as. Prefix queries return None: their term set is whatever the local dictionary happens to contain, so two shards would gather statistics for different terms and neither result would be right. Callers that need global statistics must reject or rewrite prefix queries rather than silently produce a mixed ranking.

    tokenize

    fn tokenize(text : String) -> Array[Token]

    Convenience: analyze with the default analyzer.

    wal_decode

    fn wal_decode(data : Bytes) -> Array[WalEntry] raise CodecError

    Decode a WAL image, replaying every complete entry. The "MWL1" header may appear at the start and again after any entry (each append batch to a fresh file carries one); a torn header tail is ignored. Stops silently at a torn or corrupt entry tail (crash recovery), including a frame whose type byte is not a known entry kind; raises only if the leading header is not a WAL or a mid-stream header is corrupt.

    wal_encode

    fn wal_encode(entries : Array[WalEntry]) -> Bytes

    Encode entries into a WAL image. A non-empty log starts with the "MWL1" header; an empty log is empty bytes (so appending the first entry to a fresh file also writes the header exactly once).

    write_double

    fn write_double(buf : Array[Byte], value : Double) -> Unit

    write_string

    fn write_string(buf : Array[Byte], s : String) -> Unit

    write_u32_le

    fn write_u32_le(buf : Array[Byte], value : UInt) -> Unit

    Append a little-endian uint32 (used for the trailing checksum).

    write_varint

    fn write_varint(buf : Array[Byte], value : Int) -> Unit

    Append an unsigned varint (LEB128) to the buffer. Every byte except the last has the continuation bit (0x80) set. Negative values are reinterpreted as their unsigned 32-bit bit pattern, so every Int32 input produces a well-formed stream a reader can round trip; the old behavior emitted a lone 0xFF that silently misaligned every following byte.