 README
- ::equalCodecError::equal
- ::not_equalCodecError::not_equal
- ::outputCodecError::output
- ::to_reprCodecError::to_repr
- ::to_stringCodecError::to_string
- ::equalQueryError::equal
- ::not_equalQueryError::not_equal
- ::outputQueryError::output
- ::to_reprQueryError::to_repr
- ::to_stringQueryError::to_string
- ::equalStoreError::equal
- ::not_equalStoreError::not_equal
- ::outputStoreError::output
- ::to_reprStoreError::to_repr
- ::to_stringStoreError::to_string
- ::equalAggResult::equal
- ::not_equalAggResult::not_equal
- ::to_jsonAggResult::to_json
- ::to_reprAggResult::to_repr
- ::equalAggSpec::equal
- ::not_equalAggSpec::not_equal
- ::to_reprAggSpec::to_repr
- ::analyzeAnalyzer::analyze
- ::defaultAnalyzer::default
- ::equalAnalyzer::equal
- ::not_equalAnalyzer::not_equal
- ::to_reprAnalyzer::to_repr
- ::from_termsBkTree::from_terms
- ::insertBkTree::insert
- ::lenBkTree::len
- ::newBkTree::new
- ::searchBkTree::search
- ::equalBlockMaxResult::equal
- ::not_equalBlockMaxResult::not_equal
- ::to_reprBlockMaxResult::to_repr
- ::defaultBm25Params::default
- ::equalBm25Params::equal
- ::not_equalBm25Params::not_equal
- ::to_reprBm25Params::to_repr
- ::appendByteWriter::append
- ::lengthByteWriter::length
- ::newByteWriter::new
- ::pushByteWriter::push
- ::push_bytesByteWriter::push_bytes
- ::to_bytesByteWriter::to_bytes
- ::write_doubleByteWriter::write_double
- ::write_stringByteWriter::write_string
- ::write_u32_leByteWriter::write_u32_le
- ::write_varintByteWriter::write_varint
- ::diffDocScores::diff
- ::emptyDocScores::empty
- ::from_pairsDocScores::from_pairs
- ::interDocScores::inter
- ::is_emptyDocScores::is_empty
- ::lengthDocScores::length
- ::pushDocScores::push
- ::unionDocScores::union
- ::equalDocument::equal
- ::not_equalDocument::not_equal
- ::to_reprDocument::to_repr
- ::equalExplanation::equal
- ::not_equalExplanation::not_equal
- ::to_jsonExplanation::to_json
- ::to_reprExplanation::to_repr
- ::equalExternalStats::equal
- ::newExternalStats::new
- ::not_equalExternalStats::not_equal
- ::to_reprExternalStats::to_repr
- ::equalFacetCount::equal
- ::not_equalFacetCount::not_equal
- ::to_jsonFacetCount::to_json
- ::to_reprFacetCount::to_repr
- ::equalFacetFilter::equal
- ::not_equalFacetFilter::not_equal
- ::to_jsonFacetFilter::to_json
- ::to_reprFacetFilter::to_repr
- ::equalFacetedResult::equal
- ::not_equalFacetedResult::not_equal
- ::to_jsonFacetedResult::to_json
- ::to_reprFacetedResult::to_repr
- ::equalFieldSchema::equal
- ::not_equalFieldSchema::not_equal
- ::to_reprFieldSchema::to_repr
- TFieldStats
- ::equalFusion::equal
- ::not_equalFusion::not_equal
- ::to_reprFusion::to_repr
- ::equalFuzzyMatch::equal
- ::not_equalFuzzyMatch::not_equal
- ::to_reprFuzzyMatch::to_repr
- ::equalHighlightSpan::equal
- ::not_equalHighlightSpan::not_equal
- ::to_reprHighlightSpan::to_repr
- ::equalHit::equal
- ::not_equalHit::not_equal
- ::to_jsonHit::to_json
- ::to_reprHit::to_repr
- ::max_layerHnswGraph::max_layer
- ::searchHnswGraph::search
- ::sizeHnswGraph::size
- THnswPoints
- ::equalHybridHit::equal
- ::not_equalHybridHit::not_equal
- ::to_reprHybridHit::to_repr
- ::addIndex::add
- ::agg_valuesIndex::agg_values
- ::aggregateIndex::aggregate
- ::all_live_scoresIndex::all_live_scores
- ::analyzerIndex::analyzer
- ::and_terms_topkIndex::and_terms_topk
- ::bk_treeIndex::bk_tree
- ::bm25Index::bm25
- ::collect_hitsIndex::collect_hits
- ::countIndex::count
- ::deleteIndex::delete
- ::doc_countIndex::doc_count
- ::doc_freqIndex::doc_freq
- ::doc_idIndex::doc_id
- ::explainIndex::explain
- ::field_doc_countIndex::field_doc_count
- ::field_length_totalIndex::field_length_total
- ::field_lengthsIndex::field_lengths
- ::from_bytesIndex::from_bytes
- ::fuzzy_searchIndex::fuzzy_search
- ::fuzzy_termsIndex::fuzzy_terms
- ::fuzzy_terms_fastIndex::fuzzy_terms_fast
- ::get_documentIndex::get_document
- ::get_facetsIndex::get_facets
- ::get_fieldIndex::get_field
- ::get_vectorIndex::get_vector
- ::has_external_statsIndex::has_external_stats
- ::highlightIndex::highlight
- ::highlight_spansIndex::highlight_spans
- ::hnsw_graphIndex::hnsw_graph
- ::hybrid_searchIndex::hybrid_search
- ::is_deletedIndex::is_deleted
- ::knnIndex::knn
- ::knn_exactIndex::knn_exact
- ::knn_exact_idsIndex::knn_exact_ids
- ::knn_recallIndex::knn_recall
- ::loadIndex::load
- ::load_or_createIndex::load_or_create
- ::newIndex::new
- ::num_columnIndex::num_column
- ::num_ofIndex::num_of
- ::numeric_fieldsIndex::numeric_fields
- ::or_terms_topkIndex::or_terms_topk
- ::or_walk_paysIndex::or_walk_pays
- ::postings_ofIndex::postings_of
- ::saveIndex::save
- ::schemaIndex::schema
- ::searchIndex::search
- ::search_afterIndex::search_after
- ::search_exactIndex::search_exact
- ::search_facetedIndex::search_faceted
- ::search_sortedIndex::search_sorted
- ::set_external_statsIndex::set_external_stats
- ::set_facetsIndex::set_facets
- ::set_numIndex::set_num
- ::set_vectorIndex::set_vector
- ::slot_countIndex::slot_count
- ::snippetIndex::snippet
- ::suggestIndex::suggest
- ::term_countIndex::term_count
- ::term_topk_blockmaxIndex::term_topk_blockmax
- ::terms_ofIndex::terms_of
- ::to_bytesIndex::to_bytes
- ::tokens_inIndex::tokens_in
- ::vector_countIndex::vector_count
- ::vector_dimIndex::vector_dim
- ::vector_fieldsIndex::vector_fields
- ::equalJournalDoc::equal
- ::not_equalJournalDoc::not_equal
- ::to_reprJournalDoc::to_repr
- ::equalJournalEntry::equal
- ::not_equalJournalEntry::not_equal
- ::to_reprJournalEntry::to_repr
- ::equalPosting::equal
- ::not_equalPosting::not_equal
- ::to_reprPosting::to_repr
- ::equalQToken::equal
- ::not_equalQToken::not_equal
- ::to_reprQToken::to_repr
- ::equalQuery::equal
- ::not_equalQuery::not_equal
- ::to_reprQuery::to_repr
- ::newReader::new
- ::read_byteReader::read_byte
- ::read_doubleReader::read_double
- ::read_stringReader::read_string
- ::read_u32_leReader::read_u32_le
- ::read_varintReader::read_varint
- ::remainingReader::remaining
- ::equalScoreDetail::equal
- ::not_equalScoreDetail::not_equal
- ::to_jsonScoreDetail::to_json
- ::to_reprScoreDetail::to_repr
- ::defaultSearchOptions::default
- ::equalSearchOptions::equal
- ::not_equalSearchOptions::not_equal
- ::to_jsonSearchOptions::to_json
- ::to_reprSearchOptions::to_repr
- ::addSegmentedIndex::add
- ::add_durableSegmentedIndex::add_durable
- ::checkpointSegmentedIndex::checkpoint
- ::deleteSegmentedIndex::delete
- ::delete_durableSegmentedIndex::delete_durable
- ::doc_countSegmentedIndex::doc_count
- ::flushSegmentedIndex::flush
- ::from_bytesSegmentedIndex::from_bytes
- ::get_documentSegmentedIndex::get_document
- ::get_fieldSegmentedIndex::get_field
- ::mergeSegmentedIndex::merge
- ::newSegmentedIndex::new
- ::open_or_createSegmentedIndex::open_or_create
- ::searchSegmentedIndex::search
- ::segment_countSegmentedIndex::segment_count
- ::to_bytesSegmentedIndex::to_bytes
- ::equalSortOrder::equal
- ::not_equalSortOrder::not_equal
- ::to_reprSortOrder::to_repr
- ::equalStatSummary::equal
- ::not_equalStatSummary::not_equal
- ::to_jsonStatSummary::to_json
- ::to_reprStatSummary::to_repr
- ::equalToken::equal
- ::not_equalToken::not_equal
- ::to_reprToken::to_repr
- ::equalWalEntry::equal
- ::not_equalWalEntry::not_equal
- ::to_reprWalEntry::to_repr
- VBLOCK_SIZE
- Vbuild_hnsw
- Vcompare_numeric
- Vcosine_distance
- Vcrc32
- Vdamerau_levenshtein
- Vdamerau_levenshtein_bounded
- Vexplain_terms
- Vfuse_rankings
- Vis_missing_number
- Vjournal_append
- Vjournal_append_bytes
- Vjournal_append_entry
- Vjournal_append_many
- Vjournal_checkpoint
- Vjournal_decode
- Vjournal_encode
- Vjournal_frame
- Vjournal_has_snapshot
- Vjournal_load_snapshot
- Vjournal_replay
- Vlevenshtein
- Vparse_query
- Vpercentiles_of
- Vquery_terms
- Vscoring_terms
- Vtokenize
- Vwal_decode
- Vwal_encode
- Vwrite_double
- Vwrite_string
- Vwrite_u32_le
- Vwrite_varint
moonseek
Full-text search platform in pure MoonBit: inverted index, BM25, exact and sloppy phrases, dictionary-free Chinese tokenization, fuzzy search, highlighting, facets, numeric aggregations, HNSW vector search with hybrid fusion, an HTTP service, and a distributed cluster with consistent hashing, scatter-gather on global statistics, write replication, failover, cross-shard aggregations and hybrid retrieval that equal a single node, online rebalancing, replica repair and several coordinators. One snapshot format across native/WASM/JS.
#moonseek


#Why moonseek
#Features
- Inverted index with per-field weights (e.g. title ×3, body ×1)
- BM25 ranking with configurable k1 / b
- Chinese + English tokenization: Latin words with stop-word removal; CJK overlapping bigrams (Lucene CJKAnalyzer strategy) — no dictionary needed
- Rich query syntax: term, "exact phrase", "a b"~3 (sloppy phrase: up to 3 tokens between terms), AND / OR / NOT, field:term, prefix*, parentheses, implicit AND
- Fuzzy search: Levenshtein / Damerau-Levenshtein edit distance with early-exit bounded DP; BK-tree for sub-linear lookup (13–1780× faster than linear scan on a 24k-term vocabulary)
- Did-you-mean: frequency-weighted spelling correction (suggest)
- Faceted search: exact-match facet fields, AND/OR filters, per-facet value counts, offset pagination (search_faceted)
- Ranking control: configurable sort — score, id, or a numeric field, in either direction, over HTTP as sort=num:year&order=desc and in the library as search_sorted; cursor pagination (search_after); per-term BM25 breakdown (explain). A cross-shard numeric sort is exact: the shards ship the key
- Server-side highlighting: highlight / snippet with HTML escaping, CJK-aware codepoint spans, overlap merging, densest-window extraction
- Stored fields: original texts kept in the index, retrievable via get_document / get_field, survive snapshots
- Segmented index: immutable segments + tiered merge policy + cross-segment search with latest-version-wins (SegmentedIndex)
- Write-ahead log: CRC-framed entries, torn-tail recovery, durable add + atomic checkpoint + crash-safe reopen (native)
- Crash-safe persistence: versioned snapshot + CRC-32 checksum; atomic save (temp file → fsync → rename); torn/corrupt files are rejected, never silently loaded
- Portable: pure MoonBit core (no FFI in the engine); native file store via moonbitlang/async; browser export via WasmGC + js-string builtins. One snapshot format, two backends: an index built by the native binary loads byte-for-byte into the browser's wasm-gc build
- Measured quality, not just latency: NDCG@10 / MRR@10 / Recall@20 over 3,698 real packages with a 6-way ablation (docs/quality.md)
- HTTP service: a REST search API (docs/api.md) with bulk ingest, facets, aggregations, highlighting, explain, suggest and vector queries. The console in console/ drives it
- Durable service: --data-dir journals every accepted write (CRC-framed, data fsync) before applying it and checkpoints atomically, so a restart replays text, facets, numbers, vectors and deletions exactly. One fsync per bulk batch keeps durable ingest within ~1.2–1.3× of in-memory, and concurrent single-document writes share a flush through group commit — 1.9× at 8 writers, 3.4× at 32 over one-fsync-per-request. tools/test-durability.sh and tools/test-durability-concurrent.sh restart the process to prove it
- Distributed cluster: one binary is a node, a shard or a coordinator. Consistent hashing (a fourth shard moves 24% of the corpus, not 75%), write routing with replication to every group member, cross-shard facets, aggregations, sorts and hybrid retrieval that equal a single node, globally consistent scoring (?dfs=true reproduced a single node's ranking exactly, 8/8 queries, zero score difference), POST /_rebalance to grow without a reindex (the plan predicted 762 moves and the executor made 762, ending at exactly the predicted distribution), POST /_repair to bring a member that missed writes back in line, replica failover, and partial answers that name the shards that failed (docs/cluster.md)
- Vector search: pure-MoonBit HNSW with measured recall against brute force (0.996@ef=32, 0.999@ef=64 on 1,000 random 32-d points), plus hybrid BM25 × kNN fusion by reciprocal rank
- Numeric aggregations: terms, stats, histogram and percentiles over a result set, with numeric doc values alongside facets
- Document lifecycle: add, replace (same id), delete
#How it works
flowchart LR
  T[text] --> A[Analyzer<br/>Latin words + CJK bigrams]
  A --> I[Inverted index<br/>field → term → postings<br/>doc, freq, positions]
  Q[query string] --> P[Lexer → parser<br/>term / phrase / prefix / AND OR NOT]
  P --> E[Evaluator<br/>ascending doc arrays<br/>merge-based set ops]
  I --> E
  E --> K[Top-K selection<br/>score desc, id asc]
  K --> H[hits]
  I --> S[Snapshot MSK3<br/>CRC-32 frame]
  I --> W[WAL<br/>torn-tail recovery]
  I --> F[Facets<br/>filter + aggregation]
B[Browser<br/>WasmGC + js-string] -.-> I#Three ways to run it
moon build server --target native --release
./_build/native/release/build/server/server.exe --addr 127.0.0.1:7700 --assets console
curl -X POST localhost:7700/index/bulk --data-binary @docs.jsonl
curl "localhost:7700/search?q=parser&facets=license"for k in 0 1 2; do
./server.exe --addr 127.0.0.1:$((7801+k)) --shard-port 127.0.0.1:$((7901+k)) &
done
./server.exe --addr 127.0.0.1:7805 --shards "127.0.0.1:7901,127.0.0.1:7902,127.0.0.1:7903"
# ?dfs=true makes the ranking identical to a single node holding the whole corpus
curl "localhost:7805/search?q=parser&dfs=true"tools/demo.sh # starts it and prints the URLs
tools/demo-story.sh # or: the full story as a script (see docs/demo-video.md)./server.exe --addr 127.0.0.1:7805 --shards "…:7920,…:7921,…:7922,…:7923" # after adding the new shard
curl -X POST "localhost:7805/_rebalance?from=3"
curl -X POST "localhost:7805/_repair" # after a member comes back| 3 shards, 3,000 docs | measured |
|---|---|
| mean query p50, 6 shapes | 0.94–1.02× across four runs — the hop costs nothing measurable |
| one forwarded write (1 group, 1 member) | 1.06× |
| sequential writes, 3 groups × 2 members | 1.46×, 530 → 364 docs/s, every write acknowledged by all members |
#Quick start
let index = @moonseek.Index::new([
  { name: "title", weight: 3.0 },
  { name: "body", weight: 1.0 },
])

index.add({
  id: "doc1",
  fields: [
    ("title", "全文搜索引擎"),
    ("body", "倒排索引是搜索引擎的核心,BM25 负责排序。"),
  ],
})
index.add({
  id: "doc2",
  fields: [("title", "MoonBit"), ("body", "A fast language for WebAssembly")],
})

let hits = index.search("搜索引擎")        // [{ id: "doc1", score: … }]
let hits2 = index.search("title:moonbit")  // field-scoped
let hits3 = index.search("\"memory safety\" OR wasm*")  // phrase + prefix

// Persist (native)
index.save("index.msk")
let restored = @moonseek.Index::load("index.msk")

// Or portable bytes (works on every backend)
let image : Bytes = index.to_bytes()
let restored2 = @moonseek.Index::from_bytes(image)#CLI
moon run cmd/main -- index ./docs --index index.msk   # index .txt/.md files
moon run cmd/main -- search "搜索引擎" --index index.msk
moon run cmd/main -- search "title:rust" --limit 5
moon run cmd/main -- info --index index.msk#Browser demo
moon build --target wasm-gc
cp _build/wasm-gc/debug/build/web/web.wasm demo/web.wasm
cd demo && python -m http.server 8000
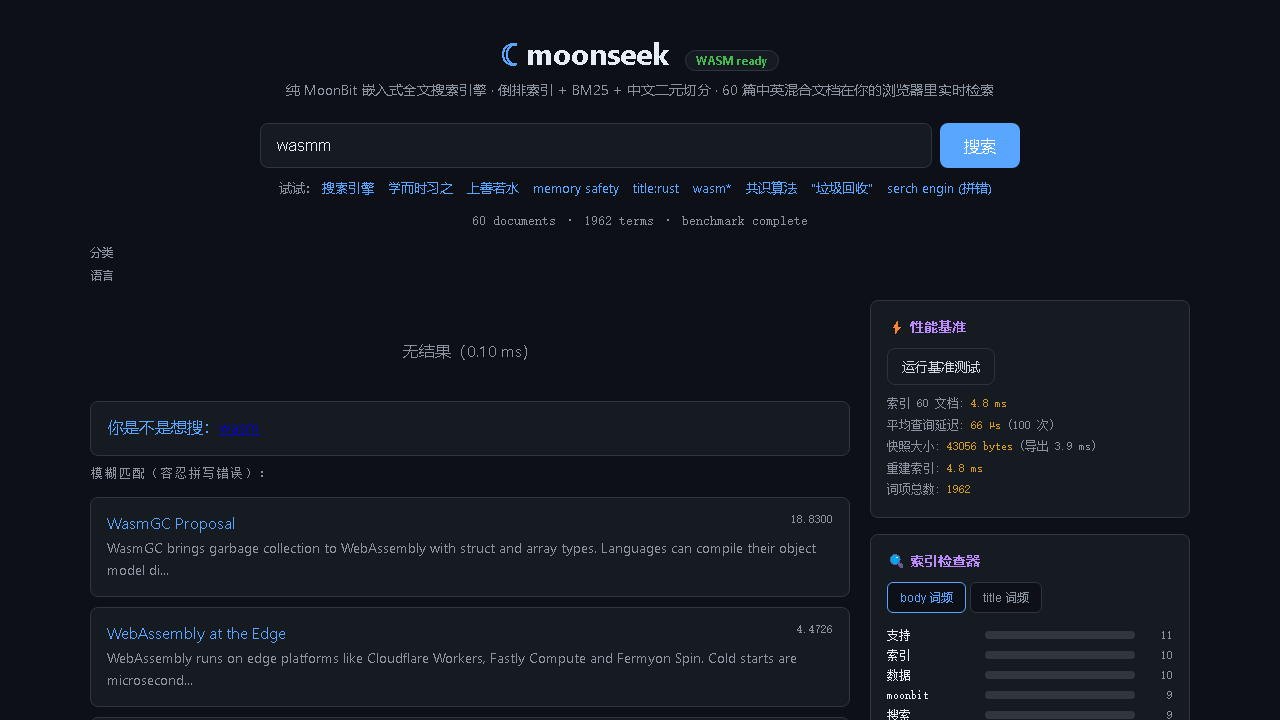
# open http://localhost:8000 (Chrome / Edge with WasmGC + js-string builtins)- Searches the real registry. Every one of the 3,698 packages published on mooncakes.io (22,837 versions) is indexed — package names, author-written keywords, descriptions, and dependency edges. The index is built by the native binary into a 1,398,936-byte (1.33 MiB) MSK3 snapshot and loaded by the wasm-gc build, which is the strongest evidence that the format is portable. Loading takes ~200 ms; the median query over a 12-query mix is 0.20 ms.
- Indexes your own files. Drag in .txt / .md / .json / .csv / .log files (or paste text) and they are parsed, tokenized and searchable immediately, with the whole index persistable to IndexedDB as one snapshot blob and reloadable without re-parsing.
- Shows its own quality. A live benchmark measures query-latency percentiles and the latency-vs-index-size curve in your browser, next to the ablation table from tools/eval: the same corpus and queries under six scoring configurations, so you can see which mechanism is worth how much NDCG.
#Performance
| Operation | Time |
|---|---|
| Index 1000 docs (with stored fields) | 85.8 ms +/- 6.2 |
| Term query (top-10) | 262 us +/- 12 |
| Phrase query (top-10) | 1.01 ms +/- 0.24 |
| Snapshot save + load | 45.3 ms +/- 2.7 |
| Operation | Time |
|---|---|
| Index build | 2.73 s -> 7,320 docs/s (median of 4) |
| Selective term (df 285) | 0.06 ms |
| Field-scoped term (df 732) | 0.13 ms |
| Saturated term (df 4,021) | 0.36 ms with block-max (see below) |
| Chinese bigram (df 4,113) | 0.37 ms |
| Boolean query | 3.02 ms |
| Exact phrase | 6.25 ms -> 0.29 ms (rarest-term walk, ~24x) |
| Sloppy phrase "a b"~3 | 9.80 ms -> 1.04 ms (~9x) |
| Prefix query seg* | 2.34 ms -> 0.44 ms (one term -> block-max) |
| Facet filter + aggregation (3,055 matches) | 14.0 ms |
| Fuzzy lookup, 23.8k terms | linear 37-46 ms -> BK-tree 0.07-2.7 ms (17-491x) |
| Snapshot 17.6 MB: serialize / load | 0.68 s / 0.75 s |
#Architecture
token.mbt      Analyzer: Latin words + CJK bigrams, positions
index.mbt      Inverted index, field stats, BM25, stored fields
query.mbt      Lexer → recursive-descent parser → evaluator
fuzzy.mbt      Levenshtein/Damerau distance, fuzzy search
suggest.mbt    Frequency-weighted did-you-mean
highlight.mbt  Server-side highlight/spans/snippet (codepoint offsets)
facet.mbt      Facet values, filters, aggregations, pagination
bktree.mbt     BK-tree for sub-linear fuzzy lookup
explain.mbt    BM25 breakdown, sort orders, cursor pagination
segment.mbt    SegmentedIndex: immutable segments + tiered merge
wal.mbt        CRC-framed write-ahead log (portable byte layer)
wal_native.mbt Durable add/checkpoint/crash recovery (native)
codec.mbt      Varint / UTF-8 / double / CRC-32 primitives
snapshot.mbt   MSK3 format: versioned payload + checksum + stored fields + facets
store.mbt      Native atomic file persistence (async/fs)
web/           Browser exports (#export_name, js-string builtins)
cmd/main/      CLI: index / search / info
examples/      Runnable examples (basic, persistence)
demo/ Single-page browser demo (60 docs, benchmarks, inspector)- docs/benchmark.md — performance whitepaper (stress numbers, methodology, limitations)
- docs/comparison.md — feature matrix vs tantivy / Lucene / bleve
#Testing
moon test                    # 355 tests (native)
moon test --target wasm-gc   # 299 tests
moon test --target js        # 299 tests
moon bench --release         # benchmarks
moon coverage analyze        # coverage report
moon run bench/stress --target native --release # 20k-doc stress benchmark#Roadmap
#License
CodecError
impl Show for CodecErrorCodecError::output
CodecError::to_string
StoreError
impl Show for StoreErrorAggResult
pub(all) struct AggResult {
field : String
kind : String
buckets : Array[(String, Double)]
stats : StatSummary?
percentiles : Array[(Double, Double)]
} derive(Eq, Debug)AggSpec
Analyzer
Analyzer::analyze
BkTree
pub struct BkTree {
  // private fields
}BkTree::from_terms
BkTree::insert
BkTree::search
BlockMaxResult
BlockMaxResult::not_equal
Bm25Params
impl Default for Bm25ParamsByteWriter
pub struct ByteWriter {
  // private fields
}ByteWriter::append
ByteWriter::to_bytes
ByteWriter::write_double
ByteWriter::write_varint
DocScores
DocScores::diff
DocScores::from_pairs
DocScores::inter
DocScores::push
Document
Explanation
pub(all) struct Explanation {
id : String
total_score : Double
details : Array[ScoreDetail]
} derive(Eq, Debug)ExternalStats
ExternalStats::new
fn ExternalStats::new(n : Int, df? : Array[((String, String), Int)], avgdl? : Array[(String, Double)]) -> ExternalStatsExternalStats::not_equal
FacetCount
FacetFilter
FacetedResult
FacetedResult::not_equal
FieldSchema
Fusion
FuzzyMatch
HighlightSpan
HighlightSpan::not_equal
Hit
HnswGraph
HnswGraph::max_layer
HnswGraph::search
fn HnswGraph::search(self : HnswGraph, points : HnswPoints, query : Array[Double], k : Int, ef? : Int) -> Array[(Int, Double)]HnswPoints
type HnswPointsHybridHit
Index
pub struct Index {
  schema : Array[FieldSchema]
  analyzer : Analyzer
  bm25 : Bm25Params
  // private fields
}Index::add
Index::agg_values
Index::aggregate
Index::all_live_scores
Index::analyzer
Index::and_terms_topk
fn Index::and_terms_topk(self : Index, terms : Array[(String, String?)], limit : Int) -> BlockMaxResult- The shortest list drives. Only documents of the most selective term can be matches, so the walk visits them and asks the other terms whether they occur at that document. A saturated term is never enumerated.
- A block whose bound cannot reach the threshold is skipped. The bound is the sum, over the terms, of each term's own block maximum — a document in the block must be in every term, so its total score cannot exceed that sum. The test is strict, so a document that only ties is still scored and can still win the id tiebreak.
Index::bk_tree
Index::bm25
Index::collect_hits
Index::count
Index::delete
Index::doc_freq
Index::doc_id
Index::explain
Index::field_doc_count
Index::field_length_total
Index::field_lengths
Index::from_bytes
Index::fuzzy_search
fn Index::fuzzy_search(self : Index, term : String, max_distance? : Int, limit? : Int) -> Array[Hit] raise QueryErrorIndex::fuzzy_terms
fn Index::fuzzy_terms(self : Index, term : String, max_distance? : Int, field? : String?) -> Array[FuzzyMatch]Index::fuzzy_terms_fast
fn Index::fuzzy_terms_fast(self : Index, term : String, max_distance? : Int, field? : String?) -> Array[FuzzyMatch]Index::get_document
Index::get_facets
Index::get_field
Index::get_vector
Index::has_external_stats
Index::highlight
fn Index::highlight(self : Index, id : String, field : String, query : String, pre_tag? : String, post_tag? : String) -> String raise QueryErrorIndex::highlight_spans
fn Index::highlight_spans(self : Index, id : String, field : String, query : String) -> Array[HighlightSpan] raise QueryErrorIndex::hnsw_graph
Index::hybrid_search
Index::is_deleted
Index::knn
Index::knn_exact
Index::knn_exact_ids
Index::knn_recall
Index::load
Index::load_or_create
async fn Index::load_or_create(path : String, schema : Array[FieldSchema]) -> Index raise StoreErrorIndex::new
Index::num_column
Index::num_of
Index::numeric_fields
Index::or_terms_topk
fn Index::or_terms_topk(self : Index, terms : Array[(String, String?)], limit : Int) -> BlockMaxResultIndex::or_walk_pays
- a dense operand — so the threshold is set high by a term with postings in every block, giving the sparse terms' blocks something to fall below;
- a much rarer operand — so most blocks contain none of it and the summed bound really does drop below the threshold.
Index::postings_of
Index::save
Index::schema
Index::search
Index::search_after
fn Index::search_after(self : Index, query : String, after_score~ : Double, after_id~ : String, limit? : Int) -> Array[Hit] raise QueryErrorIndex::search_exact
Index::search_faceted
fn Index::search_faceted(self : Index, query : String, options? : SearchOptions) -> FacetedResult raise QueryErrorIndex::search_sorted
Index::set_external_stats
Index::set_facets
Index::set_num
Index::set_vector
Index::slot_count
Index::snippet
fn Index::snippet(self : Index, id : String, field : String, query : String, max_chars? : Int, pre_tag? : String, post_tag? : String) -> String raise QueryErrorIndex::suggest
Index::term_count
Index::term_topk_blockmax
fn Index::term_topk_blockmax(self : Index, field : String?, term : String, limit : Int) -> BlockMaxResultIndex::terms_of
Index::to_bytes
Index::tokens_in
Index::vector_count
Index::vector_dim
JournalDoc
JournalEntry
Posting
QToken
Query
Reader
pub struct Reader {
  data : Bytes
  pos : Int
}ScoreDetail
SearchOptions
pub(all) struct SearchOptions {
limit : Int
offset : Int
filters : Array[FacetFilter]
facet_fields : Array[String]
} derive(Eq, Debug)impl Default for SearchOptionsSearchOptions::not_equal
SegmentedIndex
pub struct SegmentedIndex {
  schema : Array[FieldSchema]
  analyzer : Analyzer
  bm25 : Bm25Params
  segments : Array[Index]
  active : Index
  segment_max_docs : Int
}SegmentedIndex::add
SegmentedIndex::add_durable
async fn SegmentedIndex::add_durable(self : SegmentedIndex, dir : String, doc : Document) -> Unit raise StoreErrorSegmentedIndex::checkpoint
SegmentedIndex::delete
SegmentedIndex::delete_durable
async fn SegmentedIndex::delete_durable(self : SegmentedIndex, dir : String, id : String) -> Bool raise StoreErrorSegmentedIndex::doc_count
SegmentedIndex::flush
SegmentedIndex::from_bytes
SegmentedIndex::get_document
SegmentedIndex::get_field
SegmentedIndex::merge
SegmentedIndex::new
SegmentedIndex::open_or_create
async fn SegmentedIndex::open_or_create(dir : String, schema : Array[FieldSchema]) -> SegmentedIndex raise StoreErrorSegmentedIndex::search
fn SegmentedIndex::search(self : SegmentedIndex, query : String, limit? : Int) -> Array[Hit] raise QueryErrorSegmentedIndex::segment_count
SegmentedIndex::to_bytes
SortOrder
StatSummary
StatSummary::to_json
Token
WalEntry
BLOCK_SIZE
let BLOCK_SIZE : Intbuild_hnsw
compare_numeric
fn compare_numeric(index : Index, field : String, left : String, right : String, forward~ : Bool) -> Intcosine_distance
damerau_levenshtein
fn damerau_levenshtein(a : String, b : String) -> Intdamerau_levenshtein_bounded
fn damerau_levenshtein_bounded(a : String, b : String, bound : Int) -> Intexplain_terms
fuse_rankings
is_missing_number
fn is_missing_number(v : Double) -> Booljournal_append
journal_append_bytes
journal_append_entry
journal_append_many
journal_checkpoint
journal_decode
journal_encode
journal_frame
journal_has_snapshot
journal_load_snapshot
journal_replay
levenshtein
fn levenshtein(a : String, b : String) -> Intparse_query
fn parse_query(input : String, analyzer? : Analyzer, fields? : Array[String]) -> Query raise QueryErrorpercentiles_of
query_terms
scoring_terms
tokenize
wal_decode
wal_encode
write_u32_le
write_varint
Install
Download zipFull-text search platform in pure MoonBit: inverted index, BM25, exact and sloppy phrases, dictionary-free Chinese tokenization, fuzzy search, highlighting, facets, numeric aggregations, HNSW vector search with hybrid fusion, an HTTP service, and a distributed cluster with consistent hashing, scatter-gather on global statistics, write replication, failover, cross-shard aggregations and hybrid retrieval that equal a single node, online rebalancing, replica repair and several coordinators. One snapshot format across native/WASM/JS.

 Apache-2.0

 Updated 8 hours ago
 109 downloads